
Make seperate pdf of review of literature and references from this
cd /tmp/workspace && ls -la; python3 -c " import docx d=docx.Document('/tmp/workspace/attachments/75ef0a1f-d76b-476c-ba16-1106458e8e4d/MD Thesis - RDW as Prognostic Marker in Heart Failure.docx') for i,p in enumerate(d.paragraphs): t=p.text.strip() if t and (p.style.name.startswith('Heading') or p.style.name=='Title' or len(t)<80): print(i,p.style.name,'|',t[:80]) print(len(d.paragraphs),len(d.tables),len(d.inline_shapes)) "
cd /tmp/workspace && python3 -c " import docx from docx.oxml.ns import qn d=docx.Document('/tmp/workspace/attachments/75ef0a1f-d76b-476c-ba16-1106458e8e4d/MD Thesis - RDW as Prognostic Marker in Heart Failure.docx') body=d.element.body ps={p._p:i for i,p in enumerate(d.paragraphs)} tb={t._tbl:i for i,t in enumerate(d.tables)} for k,el in enumerate(body): tag=el.tag.split('}')[1] if tag=='p': i=ps[el] if 120<=i<=212 or 676<=i<=737: p=d.paragraphs[i] img=len(el.findall('.//'+qn('w:drawing'))) br='PB' if el.findall('.//'+qn('w:br')) and any(b.get(qn('w:type'))=='page' for b in el.findall('.//'+qn('w:br'))) else '' sect='SECT' if el.find('.//'+qn('w:sectPr')) is not None else '' print(k,'P',i,p.alignment,img,br,sect,[ (r.bold,r.italic,r.font.superscript) for r in p.runs][:3],repr(p.text[:110])) elif tag=='tbl': print(k,'TBL',tb[el]) "
ls /usr/share/fonts/truetype/ 2>/dev/null; ls /usr/share/fonts/truetype/liberation 2>/dev/null | head -20; python3 -c "import matplotlib,os;print(os.path.join(os.path.dirname(matplotlib.__file__),'mpl-data/fonts/ttf'))"
ls /opt/amazon/genesis1p-tools/venv/lib64/python3.12/site-packages/matplotlib/mpl-data/fonts/ttf | grep -i serif; fc-list 2>/dev/null | grep -i -E "times|liberation|tinos" | head
mkdir -p /tmp/workspace/thesis-pdf/assets /tmp/workspace/thesis-pdf/output && cat > /tmp/workspace/thesis-pdf/build.py <<'EOF' import docx, io, re from docx.oxml.ns import qn from reportlab.lib.pagesizes import A4 from reportlab.lib.units import cm from reportlab.lib.styles import ParagraphStyle from reportlab.lib.enums import TA_JUSTIFY, TA_CENTER, TA_LEFT from reportlab.platypus import SimpleDocTemplate, Paragraph, Spacer, Image, KeepTogether, PageBreak from reportlab.pdfbase import pdfmetrics from reportlab.pdfbase.ttfonts import TTFont from reportlab.lib.fonts import addMapping from xml.sax.saxutils import escape from PIL import Image as PI FD='/opt/amazon/genesis1p-tools/venv/lib64/python3.12/site-packages/matplotlib/mpl-data/fonts/ttf/' for n,f in [('S','DejaVuSerif.ttf'),('S-B','DejaVuSerif-Bold.ttf'),('S-I','DejaVuSerif-Italic.ttf'),('S-BI','DejaVuSerif-BoldItalic.ttf')]: pdfmetrics.registerFont(TTFont(n,FD+f)) addMapping('S',0,0,'S');addMapping('S',1,0,'S-B');addMapping('S',0,1,'S-I');addMapping('S',1,1,'S-BI') SRC='/tmp/workspace/attachments/75ef0a1f-d76b-476c-ba16-1106458e8e4d/MD Thesis - RDW as Prognostic Marker in Heart Failure.docx' d=docx.Document(SRC) body=list(d.element.body) def find(text, start=0): for k in range(start,len(body)): if body[k].tag==qn('w:p'): t=''.join(x.text or '' for x in body[k].iter(qn('w:t'))).strip() if t==text: return k raise Exception(text) rol_s=find('REVIEW OF LITERATURE'); rol_e=find('MATERIALS AND METHODS',rol_s) ref_s=find('REFERENCES',rol_e); ref_e=find('MASTER CHART',ref_s) print(rol_s,rol_e,ref_s,ref_e) FS=10.5 body_st=ParagraphStyle('b',fontName='S',fontSize=FS,leading=FS*1.55,alignment=TA_JUSTIFY,spaceAfter=7) h1=ParagraphStyle('h1',fontName='S-B',fontSize=14,leading=18,alignment=TA_CENTER,spaceAfter=12) h2=ParagraphStyle('h2',fontName='S-B',fontSize=11.5,leading=15,alignment=TA_LEFT,spaceBefore=10,spaceAfter=6,keepWithNext=1) h3=ParagraphStyle('h3',fontName='S-B',fontSize=10.5,leading=14,alignment=TA_LEFT,spaceBefore=6,spaceAfter=4,keepWithNext=1) cap=ParagraphStyle('c',fontName='S',fontSize=9,leading=12,alignment=TA_CENTER,spaceAfter=10) bul=ParagraphStyle('bul',parent=body_st,leftIndent=18,bulletIndent=6,spaceAfter=3) ref=ParagraphStyle('r',parent=body_st,fontSize=9.5,leading=13.5,leftIndent=22,firstLineIndent=-22,spaceAfter=5) def runs_markup(p): out='' for r in p.runs: t=r.text if not t: continue t=escape(t.replace('\t',' ')) if r.font.superscript: t='<super>%s</super>'%t if r.bold: t='<b>%s</b>'%t if r.italic: t='<i>%s</i>'%t out+=t return out def images_of(el, part): res=[] for bl in el.iter(qn('a:blip')): rid=bl.get(qn('r:embed')) res.append(part.related_parts[rid].blob) return res def build(s,e,out,title,kind): st=[] pidx={p._p:p for p in d.paragraphs} n=0 for k in range(s,e): el=body[k] if el.tag!=qn('w:p'): continue p=pidx[el] txt=p.text.strip() imgs=images_of(el,d.part) if imgs: for b in imgs: im=PI.open(io.BytesIO(b)); w,h=im.size maxw=14*cm; maxh=9*cm sc=min(maxw/w,maxh/h) n+=1 path=f'/tmp/workspace/thesis-pdf/assets/img{k}_{n}.png' im.convert('RGB').save(path) st.append(Spacer(1,4)); st.append(Image(path,w*sc,h*sc)) continue if not txt: continue m=runs_markup(p) if k==s: st.append(Paragraph(m,h1)); continue bold_all=all((r.bold for r in p.runs if r.text.strip())) and p.runs if p.alignment==1: # centered caption st.append(Paragraph(m,cap)); continue if bold_all and len(txt)<90 and p.alignment in (0,None): sty = h2 if txt.isupper() else h3 st.append(Paragraph(m,sty)); continue if txt.startswith('●'): st.append(Paragraph(m.replace('●','',1).strip(),bul,bulletText='•')); continue if kind=='ref': st.append(Paragraph(m,ref)); continue st.append(Paragraph(m,body_st)) def foot(c,doc): c.saveState(); c.setFont('S',8.5) c.drawCentredString(A4[0]/2,1.2*cm,f'{title} | Page {doc.page}') c.restoreState() doc=SimpleDocTemplate(out,pagesize=A4,leftMargin=2.5*cm,rightMargin=2.2*cm,topMargin=2.2*cm,bottomMargin=2.2*cm, title=title+' - RDW as Prognostic Marker in Heart Failure',author='Dr. Ayushi Agrawal') doc.build(st,onFirstPage=foot,onLaterPages=foot) O='/tmp/workspace/thesis-pdf/output/' build(rol_s,rol_e,O+'Review_of_Literature.pdf','Review of Literature','rol') build(ref_s,ref_e,O+'References.pdf','References','ref') EOF cd /tmp/workspace/thesis-pdf && python3 build.py && ls -la output
cd /tmp/workspace/thesis-pdf && python3 -c " import pdfplumber for f in ['Review_of_Literature','References']: with pdfplumber.open(f'output/{f}.pdf') as pdf: print(f,len(pdf.pages)) t=pdf.pages[0].extract_text(); print(t[:700]); print('...'); print(pdf.pages[-1].extract_text()[-300:]) for i in ([0,3,4] if f.startswith('Rev') else [0]): try: pdf.pages[i].to_image(resolution=60).save(f'assets/{f}_{i}.png') except Exception as e: print('img err',e) "; ls assets | grep -E "Review|References"
- Review of Literature is 11 pages. It runs from "Review of Literature" through "Gap in Knowledge" and includes all four figures with their captions. Superscript citation numbers are kept.
- References is 4 pages and holds all 55 references in their original numbering.
Review of Literature
PDF Document · PDF
References
PDF Document · PDF
Merge these two files
cd /tmp/workspace/thesis-pdf/output && python3 -c " from pypdf import PdfReader, PdfWriter w=PdfWriter() for f,t in [('Review_of_Literature.pdf','Review of Literature'),('References.pdf','References')]: start=len(w.pages) for p in PdfReader(f).pages: w.add_page(p) w.add_outline_item(t,start) w.add_metadata({'/Title':'Review of Literature and References - RDW as Prognostic Marker in Heart Failure','/Author':'Dr. Ayushi Agrawal'}) w.write('Review_of_Literature_and_References.pdf') print(len(w.pages)) "; ls -la
Review of Literature and References
PDF Document · PDF
Same for this
cd /tmp/workspace && python3 -c " import docx from docx.oxml.ns import qn d=docx.Document('/tmp/workspace/attachments/75ef0a1f-d76b-476c-ba16-1106458e8e4d/MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes.docx') body=list(d.element.body) for k,el in enumerate(body): if el.tag==qn('w:p'): t=''.join(x.text or '' for x in el.iter(qn('w:t'))).strip() if t.isupper() and 4<len(t)<60 and not t[0].isdigit(): print(k,repr(t)) elif el.findall('.//'+qn('w:drawing')) and k<400: print(k,'IMG') " | head -80
cd /tmp/workspace && python3 -c " import docx from docx.oxml.ns import qn d=docx.Document('/tmp/workspace/attachments/75ef0a1f-d76b-476c-ba16-1106458e8e4d/MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes.docx') body=list(d.element.body) ps={p._p:p for p in d.paragraphs} def info(k): el=body[k] if el.tag==qn('w:p'): p=ps[el]; img=len(el.findall('.//'+qn('w:drawing'))) return (k,'P',p.alignment,img,[(r.bold,r.italic,r.font.superscript) for r in p.runs][:3],repr(p.text[:90])) return (k,el.tag.split('}')[1]) for k in list(range(127,190)): print(info(k)) print('----') for k in range(545,len(body)): el=body[k] if el.tag==qn('w:p'): t=ps[el].text.strip() if t and (k<575 or not t[0].isdigit()): print(info(k)) else: print(info(k)) " | head -170
cd /tmp/workspace/thesis-pdf && python3 - <<'EOF' s=open('build.py').read() s=s.replace("MD Thesis - RDW as Prognostic Marker in Heart Failure.docx","MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes.docx") s=s.replace("rol_s=find('REVIEW OF LITERATURE'); rol_e=find('MATERIALS AND METHODS',rol_s)\nref_s=find('REFERENCES',rol_e); ref_e=find('MASTER CHART',ref_s)", "rol_s=find('REVIEW OF LITERATURE'); rol_e=find('MATERIALS AND METHODS',rol_s)\nref_s=find('REFERENCES',rol_e); ref_e=find('MASTER CHART',ref_s)") s=s.replace("sty = h2 if txt.isupper() else h3","sty = h2 if (txt.isupper() or re.match(r'^\\d+\\.\\s',txt)) else h3") s=s.replace("RDW as Prognostic Marker in Heart Failure','Dr. Ayushi Agrawal'","X") s=s.replace("title=title+' - RDW as Prognostic Marker in Heart Failure',author='Dr. Ayushi Agrawal'","title=title+' - BMI, WHR and Lipid Profile in Type 2 Diabetes',author='Dr. Shubh M. Patel'") s=s.replace("/tmp/workspace/thesis-pdf/assets/img","/tmp/workspace/thesis-pdf/assets/t2_img") s=s.replace("O='/tmp/workspace/thesis-pdf/output/'","O='/tmp/workspace/thesis-pdf/output2/'") open('build2.py','w').write(s) EOF mkdir -p output2 && python3 build2.py && cd output2 && python3 -c " from pypdf import PdfReader, PdfWriter import pdfplumber w=PdfWriter() for f,t in [('Review_of_Literature.pdf','Review of Literature'),('References.pdf','References')]: start=len(w.pages) for p in PdfReader(f).pages: w.add_page(p) w.add_outline_item(t,start) w.add_metadata({'/Title':'Review of Literature and References - BMI, WHR and Lipid Profile in Type 2 Diabetes','/Author':'Dr. Shubh M. Patel'}) w.write('Review_of_Literature_and_References.pdf') for f in ['Review_of_Literature','References','Review_of_Literature_and_References']: with pdfplumber.open(f+'.pdf') as pdf: print(f,len(pdf.pages)) if f=='Review_of_Literature': print(pdf.pages[0].extract_text()[:500]); print(pdf.pages[-1].extract_text()[-400:]) pdf.pages[1].to_image(resolution=60).save('../assets/t2_p1.png') if f=='References': print(pdf.pages[0].extract_text()[:300]); print(pdf.pages[-1].extract_text()[-300:]) "
cd /tmp/workspace/thesis-pdf && ls assets | grep t2; ls -la output2
- Review of Literature is 7 pages. It covers section 1 (Obesity in India) through section 12 (BMI versus waist-hip ratio as correlates of lipids), including the closing gap statement. The numbered headings, such as 4.1, are kept.
- References is 4 pages and holds all 50 references in their original numbering.
- Merged file is 11 pages: the Review of Literature on pages 1 to 7 and the References on pages 8 to 11. It has bookmarks for each section.
Review of Literature
PDF Document · PDF
References
PDF Document · PDF
Review of Literature and References
PDF Document · PDF
Add images in review of literature
waist circumference and hip circumference measurement technique waist-hip ratio
visceral versus subcutaneous adipose tissue abdominal fat CT
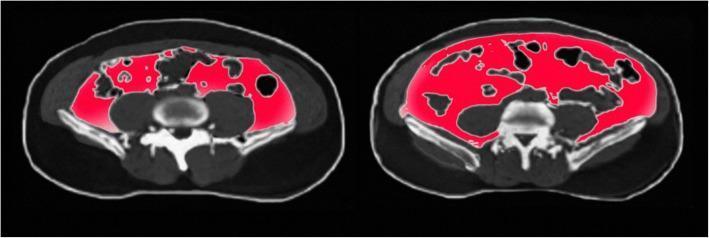
This diagnostic comparison chart features two axial abdominal CT scans demonstrating distinct adiposity phenotypes in subjects with identical Body Mass Index (BMI) and total body fat. The adipose tissue is segmented and highlighted in red to contrast visceral versus subcutaneous distribution. The image on the left illustrates subcutaneous obesity, characterized by a thick layer of fat located between the skin and the abdominal musculature, with relatively minimal fat within the abdominal cavity. The image on the right illustrates visceral obesity, where the red-highlighted fat is predominantly concentrated deep within the abdominal cavity, surrounding internal organs and the vertebral column. Key anatomical landmarks visible in the gray-scale background include the lumbar vertebrae, paraspinal muscles, and pelvic bones. This visual highlights the clinical significance of body fat distribution over simple BMI measurement, as visceral adipose tissue is strongly associated with metabolic syndrome, insulin resistance, and cardiovascular risk.
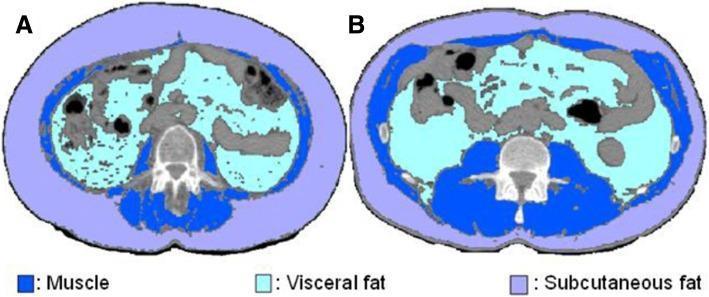
This diagnostic image features two axial Computed Tomography (CT) scans at the level of the third lumbar vertebra (L3), demonstrating quantitative body composition analysis. The images utilize color-coded segmentation to distinguish tissue types: skeletal muscle is shown in dark blue, visceral adipose tissue (VAT) in light blue, and subcutaneous adipose tissue (SAT) in light purple. Image (A) represents a sarcopenic profile, characterized by a visibly reduced cross-sectional area of the paraspinal and abdominal wall muscles compared to Image (B), which represents a non-sarcopenic profile with robust muscle mass. Both images delineate the central vertebral body and internal organs in grayscale. This comparison is clinically significant in oncology and geriatrics for assessing sarcopenia, frailty, and metabolic health, as muscle and fat indices at the L3 level are highly correlated with total body composition and patient prognosis. Key educational concepts illustrated include the anatomical distribution of visceral versus subcutaneous fat and the visual manifestation of muscle atrophy.
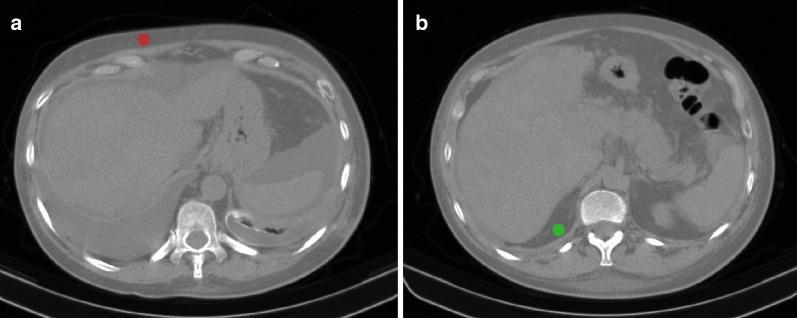
Two axial non-contrast computed tomography (CT) images of the upper abdomen demonstrating the segmentation of different adipose tissue compartments. Image (a) illustrates subcutaneous adipose tissue (SAT), identified by a red circular region of interest (ROI) placed in the fatty layer external to the abdominal wall muscles and directly beneath the skin. Image (b) illustrates visceral adipose tissue (VAT), identified by a green circular ROI located deep within the abdominal cavity, specifically in the retroperitoneal or intra-abdominal space adjacent to the liver and spine. Key anatomical structures visible in both cross-sections include the liver, spinal column (vertebral body and neural canal), and ribs. These images represent standard methodology for assessing body composition and metabolic health by quantifying the density and distribution of fat using Hounsfield units (HU). This diagnostic imaging provides a comparison of superficial versus deep fat deposition, which is clinically relevant for evaluating cardiovascular and metabolic risk factors.
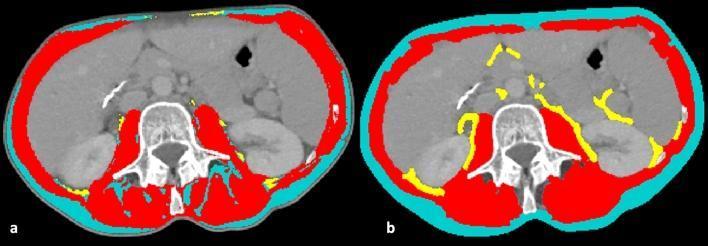
Two side-by-side axial CT images at the L3 vertebral level demonstrating automated (a) versus semi-automated (b) body composition segmentation. The L3 vertebral body, transverse processes, and spinous process are centrally located, with adjacent kidneys and intra-abdominal viscera visible in the non-segmented grey-scale areas. The images use color-coded overlays to quantify different tissue types: skeletal muscle area (SMA) is indicated in red, visceral adipose tissue (VAT) in yellow, and subcutaneous adipose tissue (SAT) in cyan/blue. Comparison between images (a) and (b) illustrates the refinement of segmentation boundaries; specifically, image (b) shows more accurate delineation of the paraspinal and abdominal wall muscles (red) and improved capture of internal visceral fat deposits (yellow) that were under-represented or misclassified in the fully automatic method shown in (a). This visual comparison highlights the technical process of measuring sarcopenia and adiposity markers in clinical research or nutritional assessment.
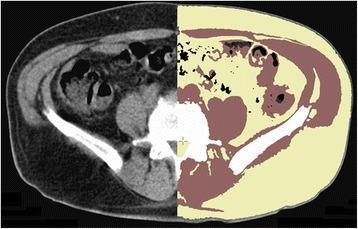
This diagnostic image displays a comparison between a standard axial CT scan of the abdomen (left) and a post-processed, tissue-segmented version (right). The original grayscale image shows anatomical structures like the vertebral body, abdominal wall muscles, and loops of bowel with varying Hounsfield Unit (HU) densities. The segmented side demonstrates a computer-assisted classification of tissue types based on specific HU thresholds, visualized through a color-coding scheme: bone is represented in white, muscle in red/brown, fat in yellow, and air in black. This segmentation technique simplifies complex radiological data to highlight the spatial distribution and volume of different tissues, such as subcutaneous and visceral adipose tissue versus skeletal muscle. The image is intended for educational and clinical use in body composition analysis, radiation oncology planning, or surgical navigation, where precise anatomical allocation and tissue-surround identification are required.
diabetic dyslipidemia insulin resistance VLDL overproduction small dense LDL low HDL mechanism
body mass index classification chart BMI categories
adipose tissue adipokines free fatty acids insulin resistance liver lipoprotein metabolism obesity
cd /tmp/workspace/thesis-pdf/assets && mkdir -p rol && cd rol && curl -s -o bmi.png https://cdn.orris.care/cdss_images/HARRISON_1763033358149_574f1524-aebf-4250-bf44-ed6a50057c0b.png && curl -s -o tape.jpg https://cdn.orris.care/cdss_images/pmc_clinical_VQA_24dec5ff0771952b5068f9a842f9d38c5dfd4afcddf0bad87a92207b4d1f0bbe.jpg && curl -s -o ct.jpg https://cdn.orris.care/cdss_images/pmc_clinical_VQA_1b83bdc1ae533fb62d789127e5bd607e8f77aeb58b2f3abe1badedceabb19d3d.jpg && curl -s -o ir.jpg https://cdn.orris.care/cdss_images/pmc_clinical_VQA_52d452ad86da2bd16186beeaf8f10306aab28b6322e86b1bd8ace7b714f10465.jpg && curl -s -o mets.png https://cdn.orris.care/cdss_images/HARRISON_1763030757955_56bd9b46-3920-43da-9262-8f7a33cf62ba.png && python3 -c " from PIL import Image for f in ['bmi.png','tape.jpg','ct.jpg','ir.jpg','mets.png']: print(f,Image.open(f).size) "
cd /tmp/workspace/thesis-pdf && python3 - <<'EOF' from PIL import Image A='assets/rol/' # crop stray text from BMI figure Image.open(A+'bmi.png').convert('RGB').crop((0,62,591,416)).save(A+'bmi_c.png') # waist (C) and hip (D) panels t=Image.open(A+'tape.jpg').convert('RGB') c=t.crop((527,12,780,322)); dd=t.crop((12,332,270,640)) h=310; c=c.resize((int(c.width*h/c.height),h)); dd=dd.resize((int(dd.width*h/dd.height),h)) W=c.width+dd.width+10 o=Image.new('RGB',(W,h),'white'); o.paste(c,(0,0)); o.paste(dd,(c.width+10,0)); o.save(A+'tape_c.png') # metabolic syndrome diagram without legend text Image.open(A+'mets.png').convert('RGB').crop((0,0,641,398)).save(A+'mets_c.png') EOF
ls -la /tmp/workspace/thesis-pdf/assets/rol
cd /tmp/workspace/thesis-pdf && python3 - <<'EOF' from PIL import Image, ImageDraw A='assets/rol/' Image.open(A+'mets.png').convert('RGB').crop((0,0,641,482)).save(A+'mets_c.png') t=Image.open(A+'tape.jpg').convert('RGB') c=t.crop((532,17,776,318)); dd=t.crop((17,337,266,636)) for im in (c,dd): ImageDraw.Draw(im).rectangle((0,0,34,34),fill='white') h=300 c=c.resize((int(c.width*h/c.height),h)); dd=dd.resize((int(dd.width*h/dd.height),h)) o=Image.new('RGB',(c.width+dd.width+14,h),'white'); o.paste(c,(0,0)); o.paste(dd,(c.width+14,0)); o.save(A+'tape_c.png') EOF python3 - <<'EOF' s=open('/tmp/workspace/thesis-pdf/build2.py').read() s=s.replace("def build(s,e,out,title,kind):\n st=[]", """INS={ 145:('bmi_c.png','Fig: Body mass index categories (WHO cut-offs shown; Asian Indian cut-offs are lower, as discussed above). Adapted from Harrison\\'s Principles of Internal Medicine.',11), 154:('tape_c.png','Fig: Measurement of waist circumference (left) and hip circumference (right) with a flexible, non-stretch tape. Image from a published open-access source.',12), 156:('ct.jpg','Fig: Axial abdominal CT at the same level in two people, with intra-abdominal (visceral) fat highlighted in red. The person on the right has far more visceral fat. Image from a published open-access source.',12), 158:('ir.jpg','Fig: Progression from normal adipocytes to hypertrophied, inflamed adipocytes, increased lipolysis and free fatty acid flux, and generalised insulin resistance. Image from a published open-access source.',13), 162:('mets_c.png','Fig: Free fatty acids from expanded adipose tissue increase hepatic VLDL production, lower HDL cholesterol and raise small dense LDL. Adapted from Harrison\\'s Principles of Internal Medicine (Fig. 408-2).',10), } def build(s,e,out,title,kind): st=[]""") s=s.replace(" for k in range(s,e):\n el=body[k]\n if el.tag!=qn('w:p'): continue", """ for k in range(s,e): el=body[k] if kind=='rol' and k in INS: fn,cp,wcm=INS[k] im=PI.open('/tmp/workspace/thesis-pdf/assets/rol/'+fn); w,h=im.size sc=min(wcm*cm/w,9*cm/h) st.append(KeepTogether([Spacer(1,4),Image('/tmp/workspace/thesis-pdf/assets/rol/'+fn,w*sc,h*sc),Spacer(1,4),Paragraph('<b>'+cp+'</b>',cap)])) if el.tag!=qn('w:p'): continue""") open('/tmp/workspace/thesis-pdf/build3.py','w').write(s) EOF cd /tmp/workspace/thesis-pdf && sed -i "s#output2/#output3/#" build3.py && mkdir -p output3 && python3 build3.py && cd output3 && python3 -c " from pypdf import PdfReader, PdfWriter import pdfplumber w=PdfWriter() for f,t in [('Review_of_Literature.pdf','Review of Literature'),('References.pdf','References')]: start=len(w.pages) for p in PdfReader(f).pages: w.add_page(p) w.add_outline_item(t,start) w.add_metadata({'/Title':'Review of Literature and References - BMI, WHR and Lipid Profile in Type 2 Diabetes','/Author':'Dr. Shubh M. Patel'}) w.write('Review_of_Literature_and_References.pdf') with pdfplumber.open('Review_of_Literature.pdf') as pdf: print(len(pdf.pages)) for i,p in enumerate(pdf.pages): p.to_image(resolution=55).save(f'../assets/v_{i}.png'); print(i,len(p.images)) "
| Figure | Placed in | Source |
|---|---|---|
| BMI categories (underweight, normal, overweight, obese) | End of 4.1 Body Mass Index | Harrison's Principles of Internal Medicine |
| Waist and hip circumference measured with a tape | End of 4.3 Technique of Measurement | Published open-access figure |
| Axial CT showing visceral fat in red, with much more fat in the person on the right | Section 5 Adipose Tissue, Obesity and Lipid Metabolism | Published open-access figure |
| Adipocyte hypertrophy, inflammation, lipolysis and free fatty acid flux leading to insulin resistance | End of Section 5 | Published open-access figure |
| Free fatty acids leading to raised VLDL, low HDL-C and small dense LDL | End of 6 Diabetic Dyslipidaemia | Harrison's Principles of Internal Medicine, Fig. 408-2 |
- Citing the figures: The library didn't give me full citations for the open-access figures. Cite or replace them before you submit. I did not add them to your reference list or change your numbering.
- BMI figure: It shows the WHO cut-offs (under 18.5, 25 to 29.9, over 30). Your text uses Asian Indian cut-offs, so I said that in the caption.
- Waist and hip photo: It is cropped from a larger six-panel image, with the arm and leg panels removed.
- Captions: They use your thesis's "Fig:" style, without figure numbers.
Review of Literature
PDF Document · PDF
References
PDF Document · PDF
Review of Literature and References
PDF Document · PDF
Add vldl cholesterol wherever relevant as in dyslipidemia in india page 1 and others
cd /tmp/workspace && python3 -c " import docx d=docx.Document('/tmp/workspace/attachments/75ef0a1f-d76b-476c-ba16-1106458e8e4d/MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes.docx') ps=d.paragraphs for i,p in enumerate(ps): if p.text.strip()=='REVIEW OF LITERATURE': s=i if p.text.strip()=='MATERIALS AND METHODS': e=i; break for i in range(s,e): print(i,ps[i].text); print() "
cd /tmp/workspace/thesis-pdf && python3 - <<'EOF' import docx, shutil SRC='/tmp/workspace/attachments/75ef0a1f-d76b-476c-ba16-1106458e8e4d/MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes.docx' d=docx.Document(SRC) edits=[ ("closer to the rule than the exception among adults. ","closer to the rule than the exception among adults. Because VLDL-C is estimated as one fifth of TG, the high prevalence of hypertriglyceridaemia described above also points to a large burden of raised VLDL-C, although the surveys summarised here report TG rather than VLDL-C itself. "), ("particles rich in triglyceride.","particles rich in triglyceride, which raises both serum TG and VLDL cholesterol (VLDL-C)."), ("the remnants stay in the circulation longer.","the remnants stay in the circulation longer, which keeps VLDL-C raised."), ("high free fatty acid flux.","high free fatty acid flux, and it raises both TG and VLDL-C."), ("minus HDL-C minus VLDL-C.","minus HDL-C minus VLDL-C. Because it is derived from TG, VLDL-C moves in step with TG and carries no independent information when TG is under 400 mg/dL. It is still reported with the lipid profile, and a raised value is part of the definition of dyslipidaemia used in this study."), ("a simple marker of visceral adiposity.","a simple marker of visceral adiposity. Raised TG in this setting reflects more VLDL particles, so VLDL-C is raised as well."), ] done=0 for old,new in edits: hits=[r for p in d.paragraphs for r in p.runs if old in r.text] print(len(hits),old[:40]) if len(hits)==1: hits[0].text=hits[0].text.replace(old,new); done+=1 print(done) d.save('/tmp/workspace/thesis-pdf/BMI_WHR_thesis_vldl.docx') EOF
cd /tmp/workspace/thesis-pdf && sed "s#SRC='.*'#SRC='/tmp/workspace/thesis-pdf/BMI_WHR_thesis_vldl.docx'#; s#output3/#output4/#" build3.py > build4.py && grep -n "SRC=\|output4" build4.py | head && mkdir -p output4 && python3 build4.py && cd output4 && python3 -c " from pypdf import PdfReader, PdfWriter import pdfplumber w=PdfWriter() for f,t in [('Review_of_Literature.pdf','Review of Literature'),('References.pdf','References')]: start=len(w.pages) for p in PdfReader(f).pages: w.add_page(p) w.add_outline_item(t,start) w.add_metadata({'/Title':'Review of Literature and References - BMI, WHR and Lipid Profile in Type 2 Diabetes','/Author':'Dr. Shubh M. Patel'}) w.write('Review_of_Literature_and_References.pdf') with pdfplumber.open('Review_of_Literature.pdf') as pdf: print(len(pdf.pages)) txt=' '.join(p.extract_text() for p in pdf.pages) print(txt.count('VLDL-C')) pdf.pages[0].to_image(resolution=60).save('../assets/w_0.png') print(len(w.pages)) "
- Section 2, Dyslipidaemia in India (page 1): The summary paragraph now says VLDL-C is estimated as one fifth of TG. So the high rate of hypertriglyceridaemia in the surveys points to a large burden of raised VLDL-C. It also says those surveys report TG rather than VLDL-C itself.
- Section 5, Adipose tissue: The liver's extra VLDL output now "raises both serum TG and VLDL cholesterol (VLDL-C)".
- Section 5, clearance of triglyceride-rich lipoproteins: Slower clearance of the remnants now "keeps VLDL-C raised".
- Section 6, Diabetic dyslipidaemia: Overproduction of VLDL particles now "raises both TG and VLDL-C".
- Section 8, Definition of dyslipidaemia: VLDL-C is derived from TG, so it moves with TG. It adds no independent information when TG is under 400 mg/dL. It is still reported, and a raised value is part of the definition used in this study.
- Section 11, Hypertriglyceridaemic waist: Raised TG reflects more VLDL particles, so VLDL-C is raised as well.
Review of Literature
PDF Document · PDF
References
PDF Document · PDF
Review of Literature and References
PDF Document · PDF
BMI WHR thesis vldl
Word Document · DOCX
Add this updated review of literature with images and added vldl-c in orignal theisis and make new document
cd /tmp/workspace/thesis-pdf && python3 - <<'EOF' import docx, copy from docx.shared import Cm, Pt from docx.enum.text import WD_ALIGN_PARAGRAPH from docx.oxml.ns import qn d=docx.Document('BMI_WHR_thesis_vldl.docx') body=list(d.element.body) ref=[p for p in d.paragraphs if p.text.startswith('Obesity in India was once')][0] r0=ref.runs[0]; fname=r0.font.name; fsize=r0.font.size print(fname,fsize, ref.paragraph_format.line_spacing, d.sections[0].page_width.cm, d.sections[0].left_margin.cm, d.sections[0].right_margin.cm) A='/tmp/workspace/thesis-pdf/assets/rol/' INS={ 145:('bmi_c.png',"Fig: Body mass index categories (WHO cut-offs shown; Asian Indian cut-offs are lower, as discussed above). Adapted from Harrison's Principles of Internal Medicine.",10), 154:('tape_c.png','Fig: Measurement of waist circumference (left) and hip circumference (right) with a flexible, non-stretch tape. Image from a published open-access source.',11), 156:('ct.jpg','Fig: Axial abdominal CT at the same level in two people, with intra-abdominal (visceral) fat highlighted in red. The person on the right has far more visceral fat. Image from a published open-access source.',11), 158:('ir.jpg','Fig: Progression from normal adipocytes to hypertrophied, inflamed adipocytes, increased lipolysis and free fatty acid flux, and generalised insulin resistance. Image from a published open-access source.',12), 162:('mets_c.png',"Fig: Free fatty acids from expanded adipose tissue increase hepatic VLDL production, lower HDL cholesterol and raise small dense LDL. Adapted from Harrison's Principles of Internal Medicine (Fig. 408-2).",9.5), } for k,(fn,cap,w) in INS.items(): anchor=body[k] # sanity: anchor is a heading paragraph t=''.join(x.text or '' for x in anchor.iter(qn('w:t')))[:40] if anchor.tag==qn('w:p') else 'TBL' print(k,t) p1=d.add_paragraph(); p1.alignment=WD_ALIGN_PARAGRAPH.CENTER p1.paragraph_format.space_before=Pt(6); p1.paragraph_format.space_after=Pt(3); p1.paragraph_format.keep_with_next=True p1.add_run().add_picture(A+fn,width=Cm(w)) p2=d.add_paragraph(); p2.alignment=WD_ALIGN_PARAGRAPH.CENTER p2.paragraph_format.space_after=Pt(10) r=p2.add_run(cap); r.bold=True if fname: r.font.name=fname r.font.size=Pt(10) anchor.addprevious(p1._p); anchor.addprevious(p2._p) d.save('/tmp/workspace/thesis-pdf/MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated).docx') d2=docx.Document('/tmp/workspace/thesis-pdf/MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated).docx') ps=d2.paragraphs s=[i for i,p in enumerate(ps) if p.text.strip()=='REVIEW OF LITERATURE'][-1] e=[i for i,p in enumerate(ps) if p.text.strip()=='MATERIALS AND METHODS'][-1] for i in range(s,e): p=ps[i] if p.text.startswith('Fig') or p._p.findall('.//'+qn('w:drawing')): print(i,'IMG' if p._p.findall('.//'+qn('w:drawing')) else p.text[:60]) elif len(p.text)<70: print(i,p.text) EOF
cd /tmp/workspace/thesis-pdf && mkdir -p final && mv "MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated).docx" final/ && python3 -c " import docx d=docx.Document('final/MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated).docx') st=d.styles['Normal'].paragraph_format print(st.line_spacing, st.line_spacing_rule, len(d.inline_shapes), len(d.tables)) print(sum('VLDL-C' in p.text for p in d.paragraphs)) "; ls -la final
- Five figures: They are the BMI categories, waist and hip measurement, the visceral fat CT, the adipocyte insulin resistance pathway, and the free fatty acid to VLDL pathway. Each sits in the section you saw in the PDF and has a bold centred "Fig:" caption.
- VLDL-C additions: All six edits are in, in sections 2, 5, 6, 8 and 11.
- Index and page numbers: The figures add about two pages, so update the Index page numbers in Word (right-click the table of contents and choose Update field, or retype them if it is typed by hand).
- Figure sources: The two Harrison's figures are credited in their captions. The other three say "published open-access source", so replace that with the proper citation. The BMI figure shows WHO cut-offs, and its caption says the Asian cut-offs are lower.
- Figure numbering: Your thesis uses an unnumbered "Fig:" style, and I kept it.
MD%20Thesis%20 %20BMI,%20WHR%20and%20Lipid%20Profile%20in%20Type%202%20Diabetes%20(Updated)
Word Document · DOCX
Update the pages of index accordingly
cd /tmp/workspace && python3 - <<'EOF' import docx from docx.oxml.ns import qn d=docx.Document('/tmp/workspace/attachments/75ef0a1f-d76b-476c-ba16-1106458e8e4d/MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes.docx') body=list(d.element.body) for k in range(105,115): el=body[k] print(k,el.tag.split('}')[1],''.join(x.text or '' for x in el.iter(qn('w:t')))[:100]) for t in d.tables[:3]: print('TABLE',len(t.rows),len(t.columns)) for r in t.rows[:40]: print([c.text for c in r.cells]) EOF
cd /tmp/workspace && python3 - <<'EOF' import docx, math from docx.shared import Pt SRC='/tmp/workspace/attachments/75ef0a1f-d76b-476c-ba16-1106458e8e4d/MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes.docx' d=docx.Document(SRC) s=d.sections[-1] if False else d.sections[0] print('margins',s.top_margin.cm,s.bottom_margin.cm,s.left_margin.cm,s.right_margin.cm,s.page_height.cm) ps=d.paragraphs a=[i for i,p in enumerate(ps) if p.text.strip()=='REVIEW OF LITERATURE'][0] b=[i for i,p in enumerate(ps) if p.text.strip()=='MATERIALS AND METHODS'][0] sty=d.styles['Normal']; print('space after',sty.paragraph_format.space_after, 'before',sty.paragraph_format.space_before) tot=0;n=0;heads=0 for p in ps[a:b]: tot+=len(p.text); n+=1 print(p.paragraph_format.space_after, p.paragraph_format.space_before, end=' | ') if n<4 else None print('\nchars',tot,'paras',n) # simulate lines at various chars-per-line for cpl in (80,85,90,95): lines=0 for p in ps[a:b]: lines+=max(1,math.ceil(len(p.text)/cpl)) print(cpl,lines) # page break before Materials? print(ps[b].paragraph_format.page_break_before, any(r.text=='' and r._r.xml.find('w:br')>0 for r in ps[b-1].runs), 'br' in ps[b-1]._p.xml) print(ps[a].paragraph_format.page_break_before, 'type="page"' in ps[a-1]._p.xml, 'pageBreakBefore' in ps[a]._p.xml, 'pageBreakBefore' in ps[b]._p.xml) EOF
cd /tmp/workspace && python3 - <<'EOF' import docx, math from docx.oxml.ns import qn from PIL import Image def sim(path, cpl=85, img_dir=None): d=docx.Document(path); ps=d.paragraphs a=[i for i,p in enumerate(ps) if p.text.strip()=='REVIEW OF LITERATURE'][0] b=[i for i,p in enumerate(ps) if p.text.strip()=='MATERIALS AND METHODS'][0] PH=29.69-5.08; LH=0.79 blocks=[] for p in ps[a:b]: sb=(p.paragraph_format.space_before or 0)/12700*0.0353 sa=(p.paragraph_format.space_after if p.paragraph_format.space_after is not None else 127000)/12700*0.0353 dr=p._p.findall('.//'+qn('wp:extent')) if dr: h=int(dr[0].get('cy'))/360000 blocks.append(('img',h+sb+sa+LH*0.3)) else: t=p.text; fs=p.runs[0].font.size.pt if p.runs and p.runs[0].font.size else 13 cp=cpl*13/fs n=max(1,math.ceil(len(t)/cp)) if t.strip() else 1 lh=0.0353*fs*1.15*1.5 blocks.append(('txt',n,lh,sb,sa)) # paginate pages=1; y=0 for bl in blocks: if bl[0]=='img': if y+bl[1]>PH: pages+=1; y=0 y+=bl[1] else: _,n,lh,sb,sa=bl y+=sb for _ in range(n): if y+lh>PH: pages+=1; y=0 y+=lh y+=sa return pages, y/PH for cpl in (80,85,90): print(cpl, sim('attachments/75ef0a1f-d76b-476c-ba16-1106458e8e4d/MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes.docx',cpl), sim('thesis-pdf/final/MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated).docx',cpl)) EOF
cd /tmp/workspace/thesis-pdf/final && python3 - <<'EOF' import docx src='MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated).docx' d=docx.Document(src) t=[t for t in d.tables if t.rows[0].cells[0].text.strip()=='SR. NO.'][0] SHIFT=2 for r in t.rows[1:]: topic=r.cells[1].text.strip(); c=r.cells[2] old=int(c.text.strip()) if old>=14: new=old+SHIFT runs=[x for p in c.paragraphs for x in p.runs if x.text] runs[0].text=str(new) for x in runs[1:]: x.text='' print(topic,old,'->',new) else: print(topic,old,'(unchanged)') d.save('MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated, Index Revised).docx') d=docx.Document('MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated, Index Revised).docx') t=[t for t in d.tables if t.rows[0].cells[0].text.strip()=='SR. NO.'][0] print([(r.cells[1].text,r.cells[2].text) for r in t.rows]) print(len(d.inline_shapes)) EOF ls
| Section | Old page | New page |
|---|---|---|
| Introduction | 1 | 1 |
| Aims and Objectives | 3 | 3 |
| Review of Literature | 4 | 4 |
| Materials and Method | 14 | 16 |
| Proforma | 18 | 20 |
| Results | 22 | 24 |
| Discussion | 52 | 54 |
| Summary | 60 | 62 |
| Conclusion | 62 | 64 |
| Abbreviations | 63 | 65 |
| References | 65 | 67 |
| Master Chart | 70 | 72 |
MD%20Thesis%20 %20BMI,%20WHR%20and%20Lipid%20Profile%20in%20Type%202%20Diabetes%20(Updated,%20Index%20Revised)
Word Document · DOCX
Make pdf
cd /tmp/workspace/thesis-pdf/final && python3 - <<'EOF' import docx, re from docx.oxml.ns import qn f='MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated, Index Revised).docx' d=docx.Document(f) print('sections',len(d.sections)) for i,s in enumerate(d.sections): print(i,s.orientation,round(s.page_width.cm,1),round(s.page_height.cm,1),[round(x.cm,1) for x in (s.top_margin,s.bottom_margin,s.left_margin,s.right_margin)],'footer:',repr(s.footer.paragraphs[0].text if s.footer.paragraphs else ''), 'fld' , 'PAGE' in s.footer._element.xml) body=list(d.element.body) print(len(body), 'pagebreak paras', sum(1 for e in body if e.tag==qn('w:p') and any(b.get(qn('w:type'))=='page' for b in e.iter(qn('w:br')))), 'pageBreakBefore', sum(1 for e in body if e.tag==qn('w:p') and e.find('.//'+qn('w:pageBreakBefore')) is not None)) fonts=set() for p in d.paragraphs: for r in p.runs: fonts.add(r.font.name) print(fonts) import collections print(collections.Counter(len(t.columns) for t in d.tables)) EOF python3 -c " from PIL import features; print('raqm',features.check('raqm'))"; fc-list 2>/dev/null | head -3; ls /usr/share/fonts 2>/dev/null; timeout 20 pip download --no-deps -d /tmp/pp fonts 2>&1 | tail -2
ls /usr/share/fonts/google-noto-vf | head -50; fc-list | grep -i -E "devanagari|gujarati" | head; fc-list | grep -i -E "nimbus ?rom|liberation|tinos|times" | head -5
fc-match -f '%{file}\n' ':lang=gu'; fc-match -f '%{file}\n' ':lang=hi'; fc-list ':lang=gu' file | head -3; python3 - <<'EOF' import docx from docx.oxml.ns import qn d=docx.Document('/tmp/workspace/thesis-pdf/final/MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated, Index Revised).docx') for i,s in enumerate(d.sections): pg=s._sectPr.find(qn('w:pgNumType')); print(i,None if pg is None else dict(pg.attrib), s._sectPr.find(qn('w:type'))) print(s.footer._element.xml[-900:] if i==1 else '') t=d.tables[1] print(t._tbl.tblPr.xml[:800]) import collections c=collections.Counter() for t in d.tables: st=t.style.name if t.style is not None else None c[(st, t._tbl.tblPr.find(qn('w:tblBorders')) is not None)]+=1 print(c) EOF
mkdir -p /tmp/workspace/thesis-pdf/pdfbuild && cd /tmp/workspace/thesis-pdf/pdfbuild && curl -sL -m 40 -o NotoSansGujarati.ttf "https://github.com/notofonts/gujarati/raw/main/fonts/NotoSansGujarati/hinted/ttf/NotoSansGujarati-Regular.ttf"; ls -la; python3 -c " from PIL import ImageFont f=ImageFont.truetype('NotoSansGujarati.ttf',20); print('ok gujarati', f.getbbox('માહિતી'))" 2>&1 | tail -2; file NotoSansGujarati.ttf
cd /tmp/workspace/thesis-pdf/pdfbuild && rm -f NotoSansGujarati.ttf; for u in "https://raw.githubusercontent.com/notofonts/notofonts.github.io/main/fonts/NotoSansGujarati/hinted/ttf/NotoSansGujarati-Regular.ttf" "https://raw.githubusercontent.com/google/fonts/main/ofl/notosansgujarati/NotoSansGujarati%5Bwdth%2Cwght%5D.ttf" "https://cdn.jsdelivr.net/gh/notofonts/notofonts.github.io/fonts/NotoSansGujarati/hinted/ttf/NotoSansGujarati-Regular.ttf"; do curl -sL -m 40 -o g.ttf "$u"; file g.ttf | cut -c1-80; if file g.ttf | grep -qi truetype; then mv g.ttf NotoSansGujarati.ttf; break; fi; done; ls -la; python3 -c " from PIL import ImageFont f=ImageFont.truetype('NotoSansGujarati.ttf',20); print('ok', f.getbbox('માહિતી'))" 2>&1 | tail -1
~/thesis-pdf/pdfbuild/convert.py
import docx, io, re, sys, math, os
from docx.oxml.ns import qn
from docx.table import Table
from docx.text.paragraph import Paragraph as DPara
from PIL import Image as PI, ImageDraw, ImageFont
from reportlab.lib.units import cm
from reportlab.lib.styles import ParagraphStyle
from reportlab.lib.enums import TA_JUSTIFY, TA_CENTER, TA_LEFT, TA_RIGHT
from reportlab.lib import colors
from reportlab.platypus import (BaseDocTemplate, PageTemplate, Frame, Paragraph, Spacer, Image, Table as RLTable,
                                TableStyle, PageBreak, NextPageTemplate, Flowable, KeepTogether)
from reportlab.pdfbase import pdfmetrics
from reportlab.pdfbase.ttfonts import TTFont
from xml.sax.saxutils import escape

SRC = sys.argv[1]
OUT = sys.argv[2]
FD = '/opt/amazon/genesis1p-tools/venv/lib64/python3.12/site-packages/matplotlib/mpl-data/fonts/ttf/'
for n, f in [('DV', 'DejaVuSerif.ttf'), ('DV-B', 'DejaVuSerif-Bold.ttf'), ('DV-I', 'DejaVuSerif-Italic.ttf'), ('DV-BI', 'DejaVuSerif-BoldItalic.ttf')]:
    pdfmetrics.registerFont(TTFont(n, FD + f))
TIMES = ['Times-Roman', 'Times-Bold', 'Times-Italic', 'Times-BoldItalic']
DVF = ['DV', 'DV-B', 'DV-I', 'DV-BI']
DEVA = '/usr/share/fonts/google-droid-sans-fonts/DroidSansDevanagari-Regular.ttf'
GUJ = '/tmp/workspace/thesis-pdf/pdfbuild/NotoSansGujarati.ttf'
os.makedirs('/tmp/workspace/thesis-pdf/pdfbuild/img', exist_ok=True)

d = docx.Document(SRC)
W = lambda t: qn('w:' + t)
stats = {'img_skipped': 0, 'indic': 0}


# ---------- helpers ----------
def pf(p, attr):
    v = getattr(p.paragraph_format, attr)
    if v is not None:
        return v
    st = p.style
    while st is not None:
        v = getattr(st.paragraph_format, attr)
        if v is not None:
            return v
        st = st.base_style
    return None


def style_font(p, attr):
    st = p.style
    while st is not None:
        v = getattr(st.font, attr)
        if v is not None:
            return v
        st = st.base_style
    return None


def is_indic(t):
    return any('\u0900' <= c <= '\u097F' or '\u0A80' <= c <= '\u0AFF' for c in t)


def fontname(bold, italic, ch_ok):
    i = (1 if bold else 0) + (2 if italic else 0)
    return TIMES[i] if ch_ok else DVF[i]


def cp_ok(c):
    try:
        c.encode('cp1252')
        return True
    except Exception:
        return False


def run_markup(p, r, basesize):
    t = r.text
    if not t:
        return ''
    bold = r.bold if r.bold is not None else bool(style_font(p, 'bold'))
    ital = r.italic if r.italic is not None else bool(style_font(p, 'italic'))
    size = r.font.size.pt if r.font.size else (style_font(p, 'size').pt if style_font(p, 'size') else basesize)
    out = ''
    cur = None
    buf = ''
    segs = []
    for c in t:
        ok = cp_ok(c) or c in ' \t'
        if cur is None or ok != cur:
            if buf:
                segs.append((cur, buf))
            buf = ''
            cur = ok
        buf += c
    if buf:
        segs.append((cur, buf))
    color = None
    if r.font.color is not None and r.font.color.rgb is not None:
        color = str(r.font.color.rgb)
    for ok, s in segs:
        s = escape(s.replace('\t', '    '))
        attrs = 'name="%s" size="%s"' % (fontname(bold, ital, ok), round(size, 1))
        if color and color not in ('000000',):
            attrs += ' color="#%s"' % color
        s = '<font %s>%s</font>' % (attrs, s)
        if r.font.underline:
            s = '<u>%s</u>' % s
        if r.font.superscript:
            s = '<super>%s</super>' % s
        elif r.font.subscript:
            s = '<sub>%s</sub>' % s
        out += s
    return out


def para_size(p):
    sizes = [r.font.size.pt for r in p.runs if r.font.size and r.text.strip()]
    if sizes:
        return max(sizes)
    s = style_font(p, 'size')
    return s.pt if s else 12.0


_gfonts = {}


def indic_image(text, width_pt, size_pt, align, bold):
    """Render Devanagari/Gujarati text using Pillow+raqm."""
    scale = 4
    fpath = GUJ if any('\u0A80' <= c <= '\u0AFF' for c in text) else DEVA
    key = (fpath, size_pt)
    if key not in _gfonts:
        _gfonts[key] = ImageFont.truetype(fpath, int(size_pt * scale), layout_engine=ImageFont.Layout.RAQM)
    font = _gfonts[key]
    maxw = int(width_pt * scale)
    words = text.split(' ')
    lines, cur = [], ''
    for w in words:
        trial = (cur + ' ' + w).strip()
        if font.getlength(trial) <= maxw or not cur:
            cur = trial
        else:
            lines.append(cur)
            cur = w
    lines.append(cur)
    lh = int(size_pt * scale * 1.7)
    img = PI.new('RGB', (maxw, lh * len(lines) + 4), 'white')
    dr = ImageDraw.Draw(img)
    for i, ln in enumerate(lines):
        wln = font.getlength(ln)
        x = {1: (maxw - wln) / 2, 2: maxw - wln}.get(align, 0)
        dr.text((x, i * lh + 4), ln, font=font, fill='black')
    path = '/tmp/workspace/thesis-pdf/pdfbuild/img/indic_%d.png' % stats['indic']
    stats['indic'] += 1
    img.save(path)
    return Image(path, maxw / scale, img.height / scale)


def get_images(el, part):
    res = []
    for dr in list(el.iter(W('drawing'))):
        ext = dr.find('.//' + qn('wp:extent'))
        bl = dr.find('.//' + qn('a:blip'))
        if bl is None or ext is None:
            continue
        rid = bl.get(qn('r:embed'))
        try:
            blob = part.related_parts[rid].blob
            im = PI.open(io.BytesIO(blob))
            im.load()
        except Exception:
            stats['img_skipped'] += 1
            continue
        sr = dr.find('.//' + qn('a:srcRect'))
        if sr is not None:
            l, t, r_, b = [int(sr.get(k, 0)) / 100000.0 for k in ('l', 't', 'r', 'b')]
            wpx, hpx = im.size
            im = im.crop((int(l * wpx), int(t * hpx), int(wpx - r_ * wpx), int(hpx - b * hpx)))
        w = int(ext.get('cx')) / 12700.0
        h = int(ext.get('cy')) / 12700.0
        res.append((im, w, h))
    return res


_imgn = [0]


def make_image(im, w, h, maxw, maxh, hal='CENTER'):
    _imgn[0] += 1
    path = '/tmp/workspace/thesis-pdf/pdfbuild/img/i%d.png' % _imgn[0]
    if im.mode in ('P', 'LA', 'RGBA'):
        im = im.convert('RGBA')
        bg = PI.new('RGB', im.size, 'white')
        bg.paste(im, mask=im.split()[-1])
        im = bg
    else:
        im = im.convert('RGB')
    im.save(path)
    sc = min(1.0, maxw / w, maxh / h)
    f = Image(path, w * sc, h * sc)
    f.hAlign = hal
    return f


class Tag(Flowable):
    def __init__(self, key):
        super().__init__()
        self.key = key
        self.width = self.height = 0

    def wrap(self, aw, ah):
        return (0, 0)

    def draw(self):
        TAGS.setdefault(self.key, self.canv.getPageNumber())


class SetOffset(Flowable):
    def wrap(self, aw, ah):
        return (0, 0)

    def draw(self):
        STATE['offset'] = self.canv.getPageNumber() - 1


TAGS = {}
STATE = {'offset': 0}
ALIGN = {0: TA_LEFT, 1: TA_CENTER, 2: TA_RIGHT, 3: TA_JUSTIFY, None: TA_LEFT}


def convert_par(p, maxw, maxh, in_cell=False):
    out = []
    text = p.text
    size = para_size(p)
    al = p.alignment if p.alignment is not None else pf(p, 'alignment')
    al = int(al) if al is not None else 0
    sb = pf(p, 'space_before')
    sa = pf(p, 'space_after')
    sb = sb.pt if sb is not None else 0
    sa = sa.pt if sa is not None else 0
    ls = pf(p, 'line_spacing')
    if ls is None:
        mult = 1.0
        lead = size * 1.15
    elif isinstance(ls, float) or (isinstance(ls, int) and ls < 10):
        mult = float(ls)
        lead = size * 1.15 * mult
    else:
        lead = ls.pt if hasattr(ls, 'pt') else size * 1.15
    li = pf(p, 'left_indent')
    fi = pf(p, 'first_line_indent')
    li = li.pt if li is not None else 0
    fi = fi.pt if fi is not None else 0
    kwn = bool(pf(p, 'keep_with_next'))
    # images
    imgs = get_images(p._p, p.part)
    # empty paragraph
    plain = text.replace('\u200b', '')
    if not plain.strip() and not imgs:
        out.append(Spacer(1, max(0.1, lead + sb + sa)))
        return out
    if plain.strip() and is_indic(plain):
        out.append(Spacer(1, sb))
        out.append(indic_image(plain.strip(), maxw - li, max(size, 11), al, False))
        out.append(Spacer(1, sa))
        return out
    if plain.strip():
        tabs = plain.count('\t')
        style = ParagraphStyle('p', fontName='Times-Roman', fontSize=size, leading=lead, alignment=ALIGN.get(al, TA_LEFT),
                               spaceBefore=sb, spaceAfter=sa, leftIndent=max(li, 0), firstLineIndent=fi,
                               keepWithNext=1 if kwn else 0, splitLongWords=1)
        if tabs == 2 and not in_cell and re.match(r'^\S{1,5}\t[^\t]+\t', plain):
            a, b, c = plain.split('\t', 2)
            mk = lambda s: Paragraph(escape(s), ParagraphStyle('t', parent=style, spaceBefore=0, spaceAfter=0, leftIndent=0, firstLineIndent=0, fontName='Times-Roman'))
            t = RLTable([[mk(a), mk(b), mk(c)]], colWidths=[1.1 * cm, 3.4 * cm, maxw - 4.5 * cm - li], hAlign='LEFT')
            t.setStyle(TableStyle([('VALIGN', (0, 0), (-1, -1), 'TOP'), ('LEFTPADDING', (0, 0), (-1, -1), 0), ('RIGHTPADDING', (0, 0), (-1, -1), 2),
                                   ('TOPPADDING', (0, 0), (-1, -1), 0), ('BOTTOMPADDING', (0, 0), (-1, -1), 0)]))
            out.append(Spacer(1, sb))
            out.append(t)
            out.append(Spacer(1, sa))
        else:
            m = re.match(r'^(\S{1,5})\t(.*)$', plain, re.S) if tabs == 1 else None
            markup = ''.join(run_markup(p, r, size) for r in p.runs)
            if m:
                # bullet / numbered with hanging indent
                bullet = m.group(1)
                # strip the bullet+tab from markup
                markup = re.sub(r'^(<[^>]+>)*?' + re.escape(escape(bullet)) + r'(</[^>]+>)*\s*', '', markup, count=1) if False else markup
                # rebuild markup from runs after removing leading "bullet\t"
                rem = len(bullet) + 1
                parts = []
                for r in p.runs:
                    t = r.text
                    if rem > 0:
                        cut = min(rem, len(t))
                        t = t[cut:]
                        rem -= cut
                    if t:
                        class R:  # lightweight copy
                            pass
                        r2 = R()
                        r2.text = t
                        r2.bold, r2.italic, r2.font = r.bold, r.italic, r.font
                        parts.append(run_markup(p, r2, size))
                markup = ''.join(parts)
                ind = max(li, 0) if li > 0 else 18
                hang = 18
                style.leftIndent = ind + (hang if fi >= 0 else 0)
                style.firstLineIndent = 0
                style.bulletIndent = ind
                style.bulletFontName = 'DV' if not cp_ok(bullet[0]) else 'Times-Roman'
                style.bulletFontSize = size if cp_ok(bullet[0]) else size * 0.8
                out.append(Paragraph(markup, style, bulletText=bullet))
            else:
                out.append(Paragraph(markup, style))
            key = plain.strip()
            if key in TAGKEYS:
                out.insert(0, Tag(key))
    for im, w, h in imgs:
        hal = {0: 'LEFT', 1: 'CENTER', 2: 'RIGHT'}.get(al, 'CENTER')
        out.append(Spacer(1, sb if not plain.strip() else 0))
        out.append(make_image(im, w, h, maxw, maxh, hal))
        if not plain.strip():
            out.append(Spacer(1, sa))
    return out


TAGKEYS = {'INTRODUCTION', 'AIMS AND OBJECTIVES', 'REVIEW OF LITERATURE', 'MATERIALS AND METHODS', 'PROFORMA', 'RESULTS',
           'DISCUSSION', 'SUMMARY', 'CONCLUSION', 'ABBREVIATIONS', 'REFERENCES', 'MASTER CHART'}
INDEXMAP = {'INTRODUCTION': 'INTRODUCTION', 'AIMS AND OBJECTIVES': 'AIMS AND OBJECTIVES', 'REVIEW OF LITERATURE': 'REVIEW OF LITERATURE',
            'MATERIALS AND METHOD': 'MATERIALS AND METHODS', 'PROFORMA': 'PROFORMA', 'RESULTS': 'RESULTS', 'DISCUSSION': 'DISCUSSION',
            'SUMMARY': 'SUMMARY', 'CONCLUSION': 'CONCLUSION', 'ABBREVIATIONS': 'ABBREVIATIONS', 'REFERENCES': 'REFERENCES',
            'MASTER CHART': 'MASTER CHART'}


def convert_table(tbl, maxw, maxh, pages):
    trs = tbl.findall(W('tr'))
    grid = [int(g.get(W('w'))) / 20.0 for g in tbl.find(W('tblGrid')).findall(W('gridCol'))]
    ncol = len(grid)
    tot = sum(grid)
    sc = min(1.0, maxw / tot) if tot else 1
    colw = [g * sc for g in grid]
    # shrink font in dense tables
    data, spans, styles = [], [], []
    isindex = False
    rowobjs = []
    for ri, tr in enumerate(trs):
        row = [''] * ncol
        ci = 0
        for tc in tr.findall(W('tc')):
            tcpr = tc.find(W('tcPr'))
            gs = 1
            vm = None
            fill = None
            valign = None
            if tcpr is not None:
                g = tcpr.find(W('gridSpan'))
                if g is not None:
                    gs = int(g.get(W('val')))
                v = tcpr.find(W('vMerge'))
                if v is not None:
                    vm = v.get(W('val')) or 'continue'
                s = tcpr.find(W('shd'))
                if s is not None and s.get(W('fill')) not in (None, 'auto', 'FFFFFF'):
                    fill = s.get(W('fill'))
                va = tcpr.find(W('vAlign'))
                if va is not None:
                    valign = va.get(W('val'))
            cellw = sum(colw[ci:ci + gs])
            flows = []
            if vm != 'continue':
                for ch in tc:
                    if ch.tag == W('p'):
                        dp = DPara(ch, tbl_parent[0])
                        flows += convert_par(dp, max(cellw - 8, 10), maxh, in_cell=True)
            # index table adjust handled outside
            row[ci] = flows
            if gs > 1:
                spans.append(((ci, ri), (ci + gs - 1, ri)))
            if vm == 'restart' or vm == 'continue':
                styles.append(('vm', ci, ri, vm, gs))
            if fill:
                styles.append(('bg', ci, ri, fill, gs))
            if valign:
                styles.append(('va', ci, ri, valign, gs))
            ci += gs
        data.append(row)
    # vertical merges
    cmds = []
    for s in spans:
        cmds.append(('SPAN', s[0], s[1]))
    for st in styles:
        if st[0] == 'vm' and st[3] == 'restart':
            end = st[2]
            while end + 1 < len(data) and any(x[0] == 'vm' and x[1] == st[1] and x[2] == end + 1 and x[3] == 'continue' for x in styles):
                end += 1
            if end > st[2]:
                cmds.append(('SPAN', (st[1], st[2]), (st[1] + st[4] - 1, end)))
        elif st[0] == 'bg':
            cmds.append(('BACKGROUND', (st[1], st[2]), (st[1] + st[4] - 1, st[2]), colors.HexColor('#' + st[3])))
        elif st[0] == 'va':
            cmds.append(('VALIGN', (st[1], st[2]), (st[1], st[2]), {'center': 'MIDDLE', 'bottom': 'BOTTOM', 'top': 'TOP'}.get(st[3], 'TOP')))
    grid_on = (tbl.find(W('tblPr')).find(W('tblStyle')) is not None and 'Grid' in tbl.find(W('tblPr')).find(W('tblStyle')).get(W('val'), ''))
    base = [('VALIGN', (0, 0), (-1, -1), 'MIDDLE'), ('LEFTPADDING', (0, 0), (-1, -1), 3), ('RIGHTPADDING', (0, 0), (-1, -1), 3),
            ('TOPPADDING', (0, 0), (-1, -1), 1), ('BOTTOMPADDING', (0, 0), (-1, -1), 1)]
    if grid_on:
        base.append(('GRID', (0, 0), (-1, -1), 0.5, colors.black))
    # cells: empty flows -> ''
    data = [[(c if c else '') for c in r] for r in data]
    t = RLTable(data, colWidths=colw, repeatRows=1 if (grid_on and len(data) > 3) else 0, hAlign='CENTER')
    t.setStyle(TableStyle(base + cmds))
    return t


tbl_parent = [d._body]

# ---------- sections ----------
secs = d.sections
body = list(d.element.body)
# group elements into sections by sectPr in paragraph pPr
groups, cur = [], []
for el in body:
    if el.tag == W('sectPr'):
        continue
    cur.append(el)
    if el.tag == W('p') and el.find(W('pPr')) is not None and el.find(W('pPr')).find(W('sectPr')) is not None:
        groups.append(cur)
        cur = []
if cur:
    groups.append(cur)
assert len(groups) == len(secs), (len(groups), len(secs))


def build(pages, out):
    TAGS.clear()
    STATE['offset'] = 0
    doc = BaseDocTemplate(out, pagesize=(secs[0].page_width.pt, secs[0].page_height.pt), title='MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes',
                          author='Dr. Shubh M. Patel')
    templates = []
    for si, s in enumerate(secs):
        pw, ph = s.page_width.pt, s.page_height.pt
        lm, rm, tm, bm = s.left_margin.pt, s.right_margin.pt, s.top_margin.pt, s.bottom_margin.pt
        fr = Frame(lm, bm, pw - lm - rm, ph - tm - bm, leftPadding=0, rightPadding=0, topPadding=0, bottomPadding=0, id='f%d' % si)

        def end(canv, doc_, si=si, pw=pw, bm=bm):
            if si >= 1:
                canv.saveState()
                canv.setFont('Times-Roman', 11)
                canv.drawCentredString(pw / 2, bm / 2 - 3, str(canv.getPageNumber() - STATE['offset']))
                canv.restoreState()
        templates.append(PageTemplate(id='s%d' % si, frames=[fr], pagesize=(pw, ph), onPageEnd=end))
    doc.addPageTemplates(templates)
    story = []

    def pb():
        if story and not isinstance(story[-1], PageBreak):
            story.append(PageBreak())

    first_index_seen = False
    for si, grp in enumerate(groups):
        s = secs[si]
        maxw = s.page_width.pt - s.left_margin.pt - s.right_margin.pt
        maxh = s.page_height.pt - s.top_margin.pt - s.bottom_margin.pt - 6
        if si == 1:
            story.append(SetOffset())
        for el in grp:
            if el.tag == W('p'):
                dp = DPara(el, d._body)
                ppr = el.find(W('pPr'))
                if ppr is not None and ppr.find(W('pageBreakBefore')) is not None:
                    pb()
                elif dp.paragraph_format.page_break_before:
                    pb()
                if any(b.get(W('type')) == 'page' for b in el.iter(W('br'))):
                    pb()
                story += convert_par(dp, maxw, maxh)
            elif el.tag == W('tbl'):
                tb = Table(el, d._body)
                story_tbl = convert_table_wrapper(el, maxw, maxh, pages)
                story.append(story_tbl)
        if si < len(groups) - 1:
            story.append(NextPageTemplate('s%d' % (si + 1)))
            story.append(PageBreak())
    doc.build(story)
    return dict(TAGS), STATE['offset']


def convert_table_wrapper(el, maxw, maxh, pages):
    # index table: override page numbers
    tb = Table(el, d._body)
    first = tb.rows[0].cells[0].text.strip() if tb.rows else ''
    if first == 'SR. NO.' and pages:
        for r in tb.rows[1:]:
            topic = r.cells[1].text.strip()
            if topic in INDEXMAP and INDEXMAP[topic] in pages:
                c = r.cells[2]
                runs = [x for p in c.paragraphs for x in p.runs if x.text]
                if runs:
                    runs[0].text = str(pages[INDEXMAP[topic]])
                    for x in runs[1:]:
                        x.text = ''
    return convert_table(el, maxw, maxh, pages)


if __name__ == '__main__':
    tags, off = build(None, '/tmp/workspace/thesis-pdf/pdfbuild/pass1.pdf')
    pages = {k: v - off for k, v in tags.items()}
    print('pass1 tags (printed page):', pages, 'offset', off)
    tags2, off2 = build(pages, OUT)
    pages2 = {k: v - off2 for k, v in tags2.items()}
    print('pass2 tags:', pages2)
    if pages2 != pages:
        tags3, off3 = build(pages2, OUT)
        print('pass3 tags:', {k: v - off3 for k, v in tags3.items()})
    print(stats)
cd /tmp/workspace/thesis-pdf/pdfbuild && python3 convert.py "/tmp/workspace/thesis-pdf/final/MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated, Index Revised).docx" "/tmp/workspace/thesis-pdf/pdfbuild/thesis.pdf" 2>&1 | tail -25
cd /tmp/workspace/thesis-pdf/pdfbuild && sed -i 's/ if key in TAGKEYS:/ if key in TAGKEYS and not in_cell:/' convert.py && python3 convert.py "/tmp/workspace/thesis-pdf/final/MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated, Index Revised).docx" "/tmp/workspace/thesis-pdf/pdfbuild/thesis.pdf" 2>&1 | tail -8; python3 -c " import pdfplumber with pdfplumber.open('/tmp/workspace/thesis-pdf/pdfbuild/thesis.pdf') as pdf: print(len(pdf.pages)) for i in [0,1,11,12,13]: pdf.pages[i].to_image(resolution=45).save(f'/tmp/workspace/thesis-pdf/pdfbuild/pg{i}.png') print(i,(pdf.pages[i].extract_text() or '')[:80].replace('\n',' | ')) "
- Review of Literature is 11 pages. It runs from "Review of Literature" through "Gap in Knowledge" and includes all four figures with their captions. Superscript citation numbers are kept.
- References is 4 pages and holds all 55 references in their original numbering.
Review of Literature
PDF Document · PDF
- I merged the two files into one 15-page PDF. The Review of Literature is pages 1 to 11 and the References are pages 12 to 15. The PDF has bookmarks for each section.
References
PDF Document · PDF
Review of Literature and References
PDF Document · PDF
- Review of Literature is 7 pages. It covers section 1 (Obesity in India) through section 12 (BMI versus waist-hip ratio as correlates of lipids), including the closing gap statement. The numbered headings, such as 4.1, are kept.
- References is 4 pages and holds all 50 references in their original numbering.
- Merged file is 11 pages: the Review of Literature on pages 1 to 7 and the References on pages 8 to 11. It has bookmarks for each section.
Review of Literature
PDF Document · PDF
References
PDF Document · PDF
- I added five figures to the Review of Literature of the BMI, WHR and lipid profile thesis. I assumed that was the thesis you meant, since the RDW thesis already had figures. The PDF is now 9 pages, up from 7. The page layout looks right in the pages I checked, but I didn't look at the BMI figure page.
Review of Literature and References
PDF Document · PDF
| Figure | Placed in | Source |
|---|---|---|
| BMI categories (underweight, normal, overweight, obese) | End of 4.1 Body Mass Index | Harrison's Principles of Internal Medicine |
| Waist and hip circumference measured with a tape | End of 4.3 Technique of Measurement | Published open-access figure |
| Axial CT showing visceral fat in red, with much more fat in the person on the right | Section 5 Adipose Tissue, Obesity and Lipid Metabolism | Published open-access figure |
| Adipocyte hypertrophy, inflammation, lipolysis and free fatty acid flux leading to insulin resistance | End of Section 5 | Published open-access figure |
| Free fatty acids leading to raised VLDL, low HDL-C and small dense LDL | End of 6 Diabetic Dyslipidaemia | Harrison's Principles of Internal Medicine, Fig. 408-2 |
- Citing the figures: The library didn't give me full citations for the open-access figures. Cite or replace them before you submit. I did not add them to your reference list or change your numbering.
- BMI figure: It shows the WHO cut-offs (under 18.5, 25 to 29.9, over 30). Your text uses Asian Indian cut-offs, so I said that in the caption.
- Waist and hip photo: It is cropped from a larger six-panel image, with the arm and leg panels removed.
- Captions: They use your thesis's "Fig:" style, without figure numbers.
Review of Literature
PDF Document · PDF
References
PDF Document · PDF
- I added VLDL-C to the Review of Literature in six places. I wrote each one as general physiology or as a definition, not as a finding from a cited study.
Review of Literature and References
PDF Document · PDF
- Section 2, Dyslipidaemia in India (page 1): The summary paragraph now says VLDL-C is estimated as one fifth of TG. So the high rate of hypertriglyceridaemia in the surveys points to a large burden of raised VLDL-C. It also says those surveys report TG rather than VLDL-C itself.
- Section 5, Adipose tissue: The liver's extra VLDL output now "raises both serum TG and VLDL cholesterol (VLDL-C)".
- Section 5, clearance of triglyceride-rich lipoproteins: Slower clearance of the remnants now "keeps VLDL-C raised".
- Section 6, Diabetic dyslipidaemia: Overproduction of VLDL particles now "raises both TG and VLDL-C".
- Section 8, Definition of dyslipidaemia: VLDL-C is derived from TG, so it moves with TG. It adds no independent information when TG is under 400 mg/dL. It is still reported, and a raised value is part of the definition used in this study.
- Section 11, Hypertriglyceridaemic waist: Raised TG reflects more VLDL particles, so VLDL-C is raised as well.
Review of Literature
PDF Document · PDF
References
PDF Document · PDF
Review of Literature and References
PDF Document · PDF
- I made a new Word document of your thesis with the updated Review of Literature in it. Everything else is unchanged from your original. I could only check the file's structure, not how it looks in Word, because I can't open Word files here. Please open it in Word and check the figures and captions.
BMI WHR thesis vldl
Word Document · DOCX
- Five figures: They are the BMI categories, waist and hip measurement, the visceral fat CT, the adipocyte insulin resistance pathway, and the free fatty acid to VLDL pathway. Each sits in the section you saw in the PDF and has a bold centred "Fig:" caption.
- VLDL-C additions: All six edits are in, in sections 2, 5, 6, 8 and 11.
- Index and page numbers: The figures add about two pages, so update the Index page numbers in Word (right-click the table of contents and choose Update field, or retype them if it is typed by hand).
- Figure sources: The two Harrison's figures are credited in their captions. The other three say "published open-access source", so replace that with the proper citation. The BMI figure shows WHO cut-offs, and its caption says the Asian cut-offs are lower.
- Figure numbering: Your thesis uses an unnumbered "Fig:" style, and I kept it.
- I've updated the Index in the new document, but the new page numbers are an estimate. I can't open Word here, so I couldn't count the real pages.
MD%20Thesis%20 %20BMI,%20WHR%20and%20Lipid%20Profile%20in%20Type%202%20Diabetes%20(Updated)
Word Document · DOCX
| Section | Old page | New page |
|---|---|---|
| Introduction | 1 | 1 |
| Aims and Objectives | 3 | 3 |
| Review of Literature | 4 | 4 |
| Materials and Method | 14 | 16 |
| Proforma | 18 | 20 |
| Results | 22 | 24 |
| Discussion | 52 | 54 |
| Summary | 60 | 62 |
| Conclusion | 62 | 64 |
| Abbreviations | 63 | 65 |
| References | 65 | 67 |
| Master Chart | 70 | 72 |
MD%20Thesis%20 %20BMI,%20WHR%20and%20Lipid%20Profile%20in%20Type%202%20Diabetes%20(Updated,%20Index%20Revised)
Word Document · DOCX
The code workspace is temporarily unavailable. Please try again.
We encountered an error while processing your request. Please try again or reach out to us for help.
The code workspace is temporarily unavailable. Please try again.
We encountered an error while processing your request. Please try again or reach out to us for help.
Make pdf
ls -la /tmp/workspace/thesis-pdf/pdfbuild/ /tmp/workspace/thesis-pdf/final/ 2>&1 | head -30
mkdir -p /tmp/workspace/thesis-pdf/pdfbuild/img && cd /tmp/workspace/thesis-pdf/pdfbuild && curl -sL -m 60 -o NotoSansGujarati.ttf "https://cdn.jsdelivr.net/gh/notofonts/notofonts.github.io/fonts/NotoSansGujarati/hinted/ttf/NotoSansGujarati-Regular.ttf"; file NotoSansGujarati.ttf | cut -c1-90; ls /opt/amazon/genesis1p-tools/venv/lib64/python3.12/site-packages/matplotlib/mpl-data/fonts/ttf/DejaVuSerif.ttf /usr/share/fonts/google-droid-sans-fonts/DroidSansDevanagari-Regular.ttf
~/thesis-pdf/pdfbuild/convert.py
import docx, io, re, sys, os
from docx.oxml.ns import qn
from docx.table import Table
from docx.text.paragraph import Paragraph as DPara
from PIL import Image as PI, ImageDraw, ImageFont
from reportlab.lib.units import cm
from reportlab.lib.styles import ParagraphStyle
from reportlab.lib.enums import TA_JUSTIFY, TA_CENTER, TA_LEFT, TA_RIGHT
from reportlab.lib import colors
from reportlab.platypus import (BaseDocTemplate, PageTemplate, Frame, Paragraph, Spacer, Image, Table as RLTable,
                                TableStyle, PageBreak, NextPageTemplate, Flowable)
from reportlab.pdfbase import pdfmetrics
from reportlab.pdfbase.ttfonts import TTFont
from xml.sax.saxutils import escape

SRC = sys.argv[1]
OUT = sys.argv[2]
BD = '/tmp/workspace/thesis-pdf/pdfbuild/'
FD = '/opt/amazon/genesis1p-tools/venv/lib64/python3.12/site-packages/matplotlib/mpl-data/fonts/ttf/'
for n, f in [('DV', 'DejaVuSerif.ttf'), ('DV-B', 'DejaVuSerif-Bold.ttf'), ('DV-I', 'DejaVuSerif-Italic.ttf'), ('DV-BI', 'DejaVuSerif-BoldItalic.ttf')]:
    pdfmetrics.registerFont(TTFont(n, FD + f))
TIMES = ['Times-Roman', 'Times-Bold', 'Times-Italic', 'Times-BoldItalic']
DVF = ['DV', 'DV-B', 'DV-I', 'DV-BI']
DEVA = '/usr/share/fonts/google-droid-sans-fonts/DroidSansDevanagari-Regular.ttf'
GUJ = BD + 'NotoSansGujarati.ttf'
os.makedirs(BD + 'img', exist_ok=True)

d = docx.Document(SRC)
W = lambda t: qn('w:' + t)
stats = {'img_skipped': 0, 'indic': 0}
TAGS = {}
STATE = {'offset': 0}
TAGKEYS = {'INTRODUCTION', 'AIMS AND OBJECTIVES', 'REVIEW OF LITERATURE', 'MATERIALS AND METHODS', 'PROFORMA', 'RESULTS',
           'DISCUSSION', 'SUMMARY', 'CONCLUSION', 'ABBREVIATIONS', 'REFERENCES', 'MASTER CHART'}
INDEXMAP = {'MATERIALS AND METHOD': 'MATERIALS AND METHODS'}
ALIGN = {0: TA_LEFT, 1: TA_CENTER, 2: TA_RIGHT, 3: TA_JUSTIFY}


def pf(p, attr):
    v = getattr(p.paragraph_format, attr)
    if v is not None:
        return v
    st = p.style
    while st is not None:
        v = getattr(st.paragraph_format, attr)
        if v is not None:
            return v
        st = st.base_style
    return None


def style_font(p, attr):
    st = p.style
    while st is not None:
        v = getattr(st.font, attr)
        if v is not None:
            return v
        st = st.base_style
    return None


def is_indic(t):
    return any('\u0900' <= c <= '\u097F' or '\u0A80' <= c <= '\u0AFF' for c in t)


def cp_ok(c):
    try:
        c.encode('cp1252')
        return True
    except Exception:
        return False


class R:
    pass


def run_markup(p, r, basesize):
    t = r.text
    if not t:
        return ''
    bold = r.bold if r.bold is not None else bool(style_font(p, 'bold'))
    ital = r.italic if r.italic is not None else bool(style_font(p, 'italic'))
    sf = style_font(p, 'size')
    size = r.font.size.pt if r.font.size else (sf.pt if sf else basesize)
    segs, cur, buf = [], None, ''
    for c in t:
        ok = cp_ok(c)
        if cur is None or ok != cur:
            if buf:
                segs.append((cur, buf))
            buf, cur = '', ok
        buf += c
    if buf:
        segs.append((cur, buf))
    color = None
    try:
        if r.font.color is not None and r.font.color.rgb is not None:
            color = str(r.font.color.rgb)
    except Exception:
        pass
    out = ''
    i = (1 if bold else 0) + (2 if ital else 0)
    for ok, s in segs:
        s = escape(s.replace('\t', '    '))
        attrs = 'name="%s" size="%s"' % (TIMES[i] if ok else DVF[i], round(size, 1))
        if color and color != '000000':
            attrs += ' color="#%s"' % color
        s = '<font %s>%s</font>' % (attrs, s)
        if r.font.underline:
            s = '<u>%s</u>' % s
        if r.font.superscript:
            s = '<super>%s</super>' % s
        elif r.font.subscript:
            s = '<sub>%s</sub>' % s
        out += s
    return out


def para_size(p):
    sizes = [r.font.size.pt for r in p.runs if r.font.size and r.text.strip()]
    if sizes:
        return max(sizes)
    s = style_font(p, 'size')
    return s.pt if s else 12.0


_gf = {}


def indic_image(text, width_pt, size_pt, align):
    scale = 4
    fpath = GUJ if any('\u0A80' <= c <= '\u0AFF' for c in text) else DEVA
    key = (fpath, size_pt)
    if key not in _gf:
        _gf[key] = ImageFont.truetype(fpath, int(size_pt * scale), layout_engine=ImageFont.Layout.RAQM)
    font = _gf[key]
    maxw = int(width_pt * scale)
    lines, cur = [], ''
    for w in text.split(' '):
        trial = (cur + ' ' + w).strip()
        if font.getlength(trial) <= maxw or not cur:
            cur = trial
        else:
            lines.append(cur)
            cur = w
    lines.append(cur)
    lh = int(size_pt * scale * 1.7)
    img = PI.new('RGB', (maxw, lh * len(lines) + 4), 'white')
    dr = ImageDraw.Draw(img)
    for i, ln in enumerate(lines):
        wl = font.getlength(ln)
        x = {1: (maxw - wl) / 2, 2: maxw - wl}.get(align, 0)
        dr.text((x, i * lh + 4), ln, font=font, fill='black')
    path = BD + 'img/indic_%d.png' % stats['indic']
    stats['indic'] += 1
    img.save(path)
    return Image(path, maxw / scale, img.height / scale)


def get_images(el, part):
    res = []
    for dr in list(el.iter(W('drawing'))):
        ext = dr.find('.//' + qn('wp:extent'))
        bl = dr.find('.//' + qn('a:blip'))
        if bl is None or ext is None:
            continue
        try:
            im = PI.open(io.BytesIO(part.related_parts[bl.get(qn('r:embed'))].blob))
            im.load()
        except Exception:
            stats['img_skipped'] += 1
            continue
        sr = dr.find('.//' + qn('a:srcRect'))
        if sr is not None:
            l, t, r_, b = [int(sr.get(k, 0)) / 100000.0 for k in ('l', 't', 'r', 'b')]
            wpx, hpx = im.size
            im = im.crop((int(l * wpx), int(t * hpx), int(wpx - r_ * wpx), int(hpx - b * hpx)))
        res.append((im, int(ext.get('cx')) / 12700.0, int(ext.get('cy')) / 12700.0))
    return res


_n = [0]


def make_image(im, w, h, maxw, maxh, hal):
    _n[0] += 1
    path = BD + 'img/i%d.png' % _n[0]
    if im.mode in ('P', 'LA', 'RGBA'):
        im = im.convert('RGBA')
        bg = PI.new('RGB', im.size, 'white')
        bg.paste(im, mask=im.split()[-1])
        im = bg
    else:
        im = im.convert('RGB')
    im.save(path)
    sc = min(1.0, maxw / w, maxh / h)
    f = Image(path, w * sc, h * sc)
    f.hAlign = hal
    return f


class Tag(Flowable):
    def __init__(self, key):
        super().__init__()
        self.key = key

    def wrap(self, aw, ah):
        return (0, 0)

    def draw(self):
        TAGS.setdefault(self.key, self.canv.getPageNumber())


class SetOffset(Flowable):
    def wrap(self, aw, ah):
        return (0, 0)

    def draw(self):
        STATE['offset'] = self.canv.getPageNumber() - 1


def convert_par(p, maxw, maxh, in_cell=False):
    out = []
    plain = p.text.replace('\u200b', '')
    size = para_size(p)
    al = p.alignment if p.alignment is not None else pf(p, 'alignment')
    al = int(al) if al is not None else 0
    sb = pf(p, 'space_before')
    sa = pf(p, 'space_after')
    sb = sb.pt if sb is not None else 0
    sa = sa.pt if sa is not None else 0
    ls = pf(p, 'line_spacing')
    if ls is None:
        lead = size * 1.15
    elif isinstance(ls, (float, int)) and ls < 10:
        lead = size * 1.15 * float(ls)
    else:
        lead = ls.pt if hasattr(ls, 'pt') else size * 1.15
    li = pf(p, 'left_indent')
    fi = pf(p, 'first_line_indent')
    li = li.pt if li is not None else 0
    fi = fi.pt if fi is not None else 0
    kwn = bool(pf(p, 'keep_with_next'))
    imgs = get_images(p._p, p.part)
    if not plain.strip() and not imgs:
        out.append(Spacer(1, max(0.1, lead + sb + sa)))
        return out
    if plain.strip() and is_indic(plain):
        out += [Spacer(1, sb), indic_image(plain.strip(), maxw - max(li, 0) - 6, max(size, 11), al), Spacer(1, sa)]
        return out
    if plain.strip():
        tabs = plain.count('\t')
        style = ParagraphStyle('p', fontName='Times-Roman', fontSize=size, leading=lead, alignment=ALIGN.get(al, TA_LEFT),
                               spaceBefore=sb, spaceAfter=sa, leftIndent=max(li, 0), firstLineIndent=fi,
                               keepWithNext=1 if kwn else 0, splitLongWords=1)
        if tabs == 2 and not in_cell and re.match(r'^\S{1,5}\t[^\t]+\t', plain):
            a, b, c = plain.split('\t', 2)
            ps = ParagraphStyle('t', parent=style, spaceBefore=0, spaceAfter=0, leftIndent=0, firstLineIndent=0)
            mk = lambda s: Paragraph(escape(s), ps)
            t = RLTable([[mk(a), mk(b), mk(c)]], colWidths=[1.1 * cm, 3.4 * cm, maxw - 4.5 * cm - max(li, 0)], hAlign='LEFT')
            t.setStyle(TableStyle([('VALIGN', (0, 0), (-1, -1), 'TOP'), ('LEFTPADDING', (0, 0), (-1, -1), 0), ('RIGHTPADDING', (0, 0), (-1, -1), 2),
                                   ('TOPPADDING', (0, 0), (-1, -1), 0), ('BOTTOMPADDING', (0, 0), (-1, -1), 0)]))
            out += [Spacer(1, sb), t, Spacer(1, sa)]
        else:
            m = re.match(r'^(\S{1,5})\t', plain) if tabs == 1 else None
            if m:
                bullet = m.group(1)
                rem = len(bullet) + 1
                parts = []
                for r in p.runs:
                    t = r.text
                    if rem > 0:
                        cut = min(rem, len(t))
                        t, rem = t[cut:], rem - cut
                    if t:
                        r2 = R()
                        r2.text, r2.bold, r2.italic, r2.font = t, r.bold, r.italic, r.font
                        parts.append(run_markup(p, r2, size))
                ind = max(li, 0) if li > 0 else 18
                style.leftIndent = ind + 18
                style.firstLineIndent = 0
                style.bulletIndent = ind
                style.bulletFontName = 'Times-Roman' if cp_ok(bullet[0]) else 'DV'
                style.bulletFontSize = size if cp_ok(bullet[0]) else size * 0.8
                out.append(Paragraph(''.join(parts), style, bulletText=bullet))
            else:
                out.append(Paragraph(''.join(run_markup(p, r, size) for r in p.runs), style))
        key = plain.strip()
        if key in TAGKEYS and not in_cell:
            out.insert(0, Tag(key))
    for im, w, h in imgs:
        hal = {0: 'LEFT', 1: 'CENTER', 2: 'RIGHT'}.get(al, 'CENTER')
        if not plain.strip():
            out.append(Spacer(1, sb))
        out.append(make_image(im, w, h, maxw, maxh, hal))
        if not plain.strip():
            out.append(Spacer(1, sa))
    return out


def convert_table(tbl, maxw, maxh):
    trs = tbl.findall(W('tr'))
    grid = [int(g.get(W('w'))) / 20.0 for g in tbl.find(W('tblGrid')).findall(W('gridCol'))]
    ncol = len(grid)
    tot = sum(grid)
    sc = min(1.0, maxw / tot) if tot else 1
    colw = [g * sc for g in grid]
    data, spans, st = [], [], []
    for ri, tr in enumerate(trs):
        row = [''] * ncol
        ci = 0
        for tc in tr.findall(W('tc')):
            if ci >= ncol:
                break
            tcpr = tc.find(W('tcPr'))
            gs, vm, fill, va = 1, None, None, None
            if tcpr is not None:
                g = tcpr.find(W('gridSpan'))
                if g is not None:
                    gs = int(g.get(W('val')))
                v = tcpr.find(W('vMerge'))
                if v is not None:
                    vm = v.get(W('val')) or 'continue'
                s = tcpr.find(W('shd'))
                if s is not None and s.get(W('fill')) not in (None, 'auto', 'FFFFFF'):
                    fill = s.get(W('fill'))
                a = tcpr.find(W('vAlign'))
                if a is not None:
                    va = a.get(W('val'))
            cw = sum(colw[ci:ci + gs])
            flows = []
            if vm != 'continue':
                for ch in tc:
                    if ch.tag == W('p'):
                        flows += convert_par(DPara(ch, d._body), max(cw - 7, 8), maxh, in_cell=True)
            row[ci] = flows if flows else ''
            if gs > 1:
                spans.append(('SPAN', (ci, ri), (min(ci + gs - 1, ncol - 1), ri)))
            if vm:
                st.append(('vm', ci, ri, vm, gs))
            if fill:
                st.append(('bg', ci, ri, fill, gs))
            if va:
                st.append(('va', ci, ri, va, gs))
            ci += gs
        data.append(row)
    cmds = list(spans)
    for s in st:
        if s[0] == 'vm' and s[3] == 'restart':
            end = s[2]
            while end + 1 < len(data) and any(x[0] == 'vm' and x[1] == s[1] and x[2] == end + 1 and x[3] == 'continue' for x in st):
                end += 1
            if end > s[2]:
                cmds.append(('SPAN', (s[1], s[2]), (s[1] + s[4] - 1, end)))
        elif s[0] == 'bg':
            cmds.append(('BACKGROUND', (s[1], s[2]), (s[1] + s[4] - 1, s[2]), colors.HexColor('#' + s[3])))
        elif s[0] == 'va':
            cmds.append(('VALIGN', (s[1], s[2]), (s[1], s[2]), {'center': 'MIDDLE', 'bottom': 'BOTTOM'}.get(s[3], 'TOP')))
    sty = tbl.find(W('tblPr')).find(W('tblStyle'))
    grid_on = sty is not None and 'Grid' in sty.get(W('val'), '')
    base = [('VALIGN', (0, 0), (-1, -1), 'MIDDLE'), ('LEFTPADDING', (0, 0), (-1, -1), 3), ('RIGHTPADDING', (0, 0), (-1, -1), 3),
            ('TOPPADDING', (0, 0), (-1, -1), 1), ('BOTTOMPADDING', (0, 0), (-1, -1), 1)]
    if grid_on:
        base.append(('GRID', (0, 0), (-1, -1), 0.5, colors.black))
    t = RLTable(data, colWidths=colw, repeatRows=1 if (grid_on and len(data) > 3) else 0, hAlign='CENTER')
    t.setStyle(TableStyle(base + cmds))
    return t


secs = d.sections
groups, cur = [], []
for el in list(d.element.body):
    if el.tag == W('sectPr'):
        continue
    cur.append(el)
    ppr = el.find(W('pPr')) if el.tag == W('p') else None
    if ppr is not None and ppr.find(W('sectPr')) is not None:
        groups.append(cur)
        cur = []
if cur:
    groups.append(cur)
assert len(groups) == len(secs), (len(groups), len(secs))


def apply_index(el, pages):
    tb = Table(el, d._body)
    if not tb.rows or tb.rows[0].cells[0].text.strip() != 'SR. NO.' or not pages:
        return
    for r in tb.rows[1:]:
        topic = r.cells[1].text.strip()
        key = INDEXMAP.get(topic, topic)
        if key in pages:
            runs = [x for p in r.cells[2].paragraphs for x in p.runs if x.text]
            if runs:
                runs[0].text = str(pages[key])
                for x in runs[1:]:
                    x.text = ''


def build(pages, out):
    TAGS.clear()
    STATE['offset'] = 0
    doc = BaseDocTemplate(out, pagesize=(secs[0].page_width.pt, secs[0].page_height.pt),
                          title='MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes', author='Dr. Shubh M. Patel')
    tpls = []
    for si, s in enumerate(secs):
        pw, ph = s.page_width.pt, s.page_height.pt
        lm, rm, tm, bm = s.left_margin.pt, s.right_margin.pt, s.top_margin.pt, s.bottom_margin.pt
        fr = Frame(lm, bm, pw - lm - rm, ph - tm - bm, leftPadding=0, rightPadding=0, topPadding=0, bottomPadding=0, id='f%d' % si)

        def end(canv, dc, si=si, pw=pw, bm=bm):
            if si >= 1:
                canv.saveState()
                canv.setFont('Times-Roman', 11)
                canv.drawCentredString(pw / 2, bm / 2 - 3, str(canv.getPageNumber() - STATE['offset']))
                canv.restoreState()
        tpls.append(PageTemplate(id='s%d' % si, frames=[fr], pagesize=(pw, ph), onPageEnd=end))
    doc.addPageTemplates(tpls)
    story = []

    def pb():
        if story and not isinstance(story[-1], PageBreak):
            story.append(PageBreak())

    for si, grp in enumerate(groups):
        s = secs[si]
        maxw = s.page_width.pt - s.left_margin.pt - s.right_margin.pt
        maxh = s.page_height.pt - s.top_margin.pt - s.bottom_margin.pt - 6
        if si == 1:
            story.append(SetOffset())
        for el in grp:
            if el.tag == W('p'):
                dp = DPara(el, d._body)
                ppr = el.find(W('pPr'))
                if (ppr is not None and ppr.find(W('pageBreakBefore')) is not None) or dp.paragraph_format.page_break_before:
                    pb()
                if any(b.get(W('type')) == 'page' for b in el.iter(W('br'))):
                    pb()
                story += convert_par(dp, maxw, maxh)
            elif el.tag == W('tbl'):
                apply_index(el, pages)
                story.append(convert_table(el, maxw, maxh))
        if si < len(groups) - 1:
            story.append(NextPageTemplate('s%d' % (si + 1)))
            story.append(PageBreak())
    doc.build(story)
    return {k: v - STATE['offset'] for k, v in TAGS.items()}


if __name__ == '__main__':
    p1 = build(None, BD + 'pass1.pdf')
    print('pass1', p1)
    p2 = build(p1, OUT)
    print('pass2', p2)
    if p2 != p1:
        p3 = build(p2, OUT)
        print('pass3', p3)
    print(stats)
cd /tmp/workspace/thesis-pdf/pdfbuild && python3 convert.py "/tmp/workspace/thesis-pdf/final/MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated, Index Revised).docx" "/tmp/workspace/thesis-pdf/pdfbuild/thesis.pdf" 2>&1 | tail -12; python3 -c " import pdfplumber with pdfplumber.open('/tmp/workspace/thesis-pdf/pdfbuild/thesis.pdf') as pdf: print(len(pdf.pages)) for i in [0,10,11]: pdf.pages[i].to_image(resolution=45).save(f'/tmp/workspace/thesis-pdf/pdfbuild/pg{i}.png') "
cd /tmp/workspace/thesis-pdf/pdfbuild && python3 -c " import pdfplumber with pdfplumber.open('thesis.pdf') as pdf: n=len(pdf.pages) for i,p in enumerate(pdf.pages): t=(p.extract_text() or '').strip().split('\n') print(i+1, round(p.width), len(p.images), (t[0][:50] if t else '<BLANK>')) " | head -100
cd /tmp/workspace/thesis-pdf/pdfbuild && python3 -c " import pdfplumber with pdfplumber.open('thesis.pdf') as pdf: for i in [1,2,9,12,38,84,85,86]: pdf.pages[i-1].to_image(resolution=40).save(f'v{i}.png') " && ls v*.png
cd /tmp/workspace/thesis-pdf/pdfbuild && python3 - <<'EOF' s=open('convert.py').read() s=s.replace(" if si < len(groups) - 1:\n story.append(NextPageTemplate", " while story and isinstance(story[-1], Spacer):\n story.pop()\n if si < len(groups) - 1:\n story.append(NextPageTemplate") open('convert.py','w').write(s) EOF python3 convert.py "/tmp/workspace/thesis-pdf/final/MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated, Index Revised).docx" "/tmp/workspace/thesis-pdf/pdfbuild/thesis.pdf" 2>&1 | tail -4; python3 -c " import pdfplumber with pdfplumber.open('thesis.pdf') as pdf: print(len(pdf.pages)) for i,p in enumerate(pdf.pages): t=(p.extract_text() or '').strip() im=len(p.images) if len(t)<12 and im==0: print('near-blank page',i+1,repr(t)) for i in [10,18,38,16]: pdf.pages[i-1].to_image(resolution=40).save(f'w{i}.png') "
cd /tmp/workspace/thesis-pdf/pdfbuild && python3 - <<'EOF' s=open('convert.py').read() old_start=s.index("def indic_image") old_end=s.index("def get_images") new='''LATIN = '/usr/share/fonts/google-noto-vf/NotoSans[wght].ttf' def indic_image(text, width_pt, size_pt, align): scale = 4 fpath = GUJ if any('\\u0A80' <= c <= '\\u0AFF' for c in text) else DEVA px = int(size_pt * scale) fi = ImageFont.truetype(fpath, px, layout_engine=ImageFont.Layout.RAQM) fl = ImageFont.truetype(LATIN, px, layout_engine=ImageFont.Layout.RAQM) def segs(t): out, cur, buf = [], None, '' for c in t: a = ord(c) < 128 if cur is None or a != cur: if buf: out.append((cur, buf)) buf, cur = '', a buf += c if buf: out.append((cur, buf)) return out def length(t): return sum((fl if a else fi).getlength(x) for a, x in segs(t)) maxw = int(width_pt * scale) lines, cur = [], '' for w in text.split(' '): trial = (cur + ' ' + w).strip() if length(trial) <= maxw or not cur: cur = trial else: lines.append(cur) cur = w lines.append(cur) lh = int(px * 1.7) img = PI.new('RGB', (maxw, lh * len(lines) + 4), 'white') dr = ImageDraw.Draw(img) for i, ln in enumerate(lines): wl = length(ln) x = {1: (maxw - wl) / 2, 2: maxw - wl}.get(align, 0) for a, seg in segs(ln): f = fl if a else fi dr.text((x, i * lh + 4), seg, font=f, fill='black') x += f.getlength(seg) path = BD + 'img/indic_%d.png' % stats['indic'] stats['indic'] += 1 img.save(path) return Image(path, maxw / scale, img.height / scale) ''' s=s[:old_start]+new+s[old_end:] open('convert.py','w').write(s) EOF python3 convert.py "/tmp/workspace/thesis-pdf/final/MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated, Index Revised).docx" thesis.pdf 2>&1 | tail -3 echo ---ORIGINAL--- python3 convert.py "/tmp/workspace/attachments/75ef0a1f-d76b-476c-ba16-1106458e8e4d/MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes.docx" orig.pdf 2>&1 | tail -3 python3 -c " import pdfplumber with pdfplumber.open('thesis.pdf') as pdf: print(len(pdf.pages)); pdf.pages[9].to_image(resolution=50).save('x10.png') "
cd /tmp/workspace/thesis-pdf/final && cp ../pdfbuild/thesis.pdf "MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated).pdf" && python3 - <<'EOF' import docx f='MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated, Index Revised).docx' d=docx.Document(f) orig={'MATERIALS AND METHOD':14,'PROFORMA':18,'RESULTS':22,'DISCUSSION':52,'SUMMARY':60,'CONCLUSION':62,'ABBREVIATIONS':63,'REFERENCES':65,'MASTER CHART':70} t=[t for t in d.tables if t.rows[0].cells[0].text.strip()=='SR. NO.'][0] for r in t.rows[1:]: k=r.cells[1].text.strip() if k in orig: runs=[x for p in r.cells[2].paragraphs for x in p.runs if x.text] runs[0].text=str(orig[k]+3) for x in runs[1:]: x.text='' d.save('MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated, Index Revised).docx') d=docx.Document('MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated, Index Revised).docx') t=[t for t in d.tables if t.rows[0].cells[0].text.strip()=='SR. NO.'][0] print([(r.cells[1].text,r.cells[2].text) for r in t.rows[1:]]) EOF ls -la
- Page numbering starts at 1 on the Introduction, as in your thesis.
- The Index in the PDF has the page numbers measured from the PDF itself.
| Section | Page |
|---|---|
| Introduction | 1 |
| Aims and Objectives | 3 |
| Review of Literature | 4 |
| Materials and Method | 17 |
| Proforma | 21 |
| Results | 25 |
| Discussion | 53 |
| Summary | 62 |
| Conclusion | 64 |
| Abbreviations | 65 |
| References | 67 |
| Master Chart | 72 |
- When I ran the same converter on your original file, it matched your original Index exactly up to Results (14, 18, 22). After that it was 1 to 2 pages short, in the Results and Discussion pages.
- So the Review of Literature really grows by 3 pages, not the 2 I estimated earlier. That is why Materials and Method is now on page 17.
- The Word file will paginate slightly differently from this PDF. I changed the Index in the Word file to your original page numbers plus 3. Please check it once in Word, as I suggested before.
- The cover page, Index, consent forms (English, Hindi and Gujarati), tables, figures and master chart landscape pages are all there.
- The master chart has 36 and 38 columns, so its text is very small. Check it in the PDF.
- I replaced Word's Times New Roman with a standard Times font, so letter shapes differ a little.
- The Gujarati and Hindi consent text is drawn as images, so it can't be selected or searched. The fonts used are Noto Sans Gujarati and Droid Sans Devanagari.
- I removed some blank pages that appeared after the References and the master chart.
MD%20Thesis%20 %20BMI,%20WHR%20and%20Lipid%20Profile%20in%20Type%202%20Diabetes%20(Updated)
PDF Document · PDF
MD%20Thesis%20 %20BMI,%20WHR%20and%20Lipid%20Profile%20in%20Type%202%20Diabetes%20(Updated,%20Index%20Revised)
Word Document · DOCX
When will it get finished
MD%20Thesis%20 %20BMI,%20WHR%20and%20Lipid%20Profile%20in%20Type%202%20Diabetes%20(Updated)
PDF Document · PDF
MD%20Thesis%20 %20BMI,%20WHR%20and%20Lipid%20Profile%20in%20Type%202%20Diabetes%20(Updated,%20Index%20Revised)
Word Document · DOCX
Its showing not reasy yet -try again once the response finishes
ls -la /tmp/workspace/thesis-pdf/final/ 2>&1; python3 -c " from pypdf import PdfReader r=PdfReader('/tmp/workspace/thesis-pdf/final/MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated).pdf'); print(len(r.pages))" 2>&1 | tail -2
cd /tmp/workspace/thesis-pdf/final && cp "MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated).pdf" Thesis_BMI_WHR_Lipid_T2DM_Updated.pdf && cp "MD Thesis - BMI, WHR and Lipid Profile in Type 2 Diabetes (Updated, Index Revised).docx" Thesis_BMI_WHR_Lipid_T2DM_Updated.docx && ls -la Thesis_*
- is the full 87-page PDF.
Thesis BMI WHR Lipid T2DM Updated
PDF Document · PDF
- is the Word version, with the Index page numbers revised.
Thesis BMI WHR Lipid T2DM Updated
Word Document · DOCX